
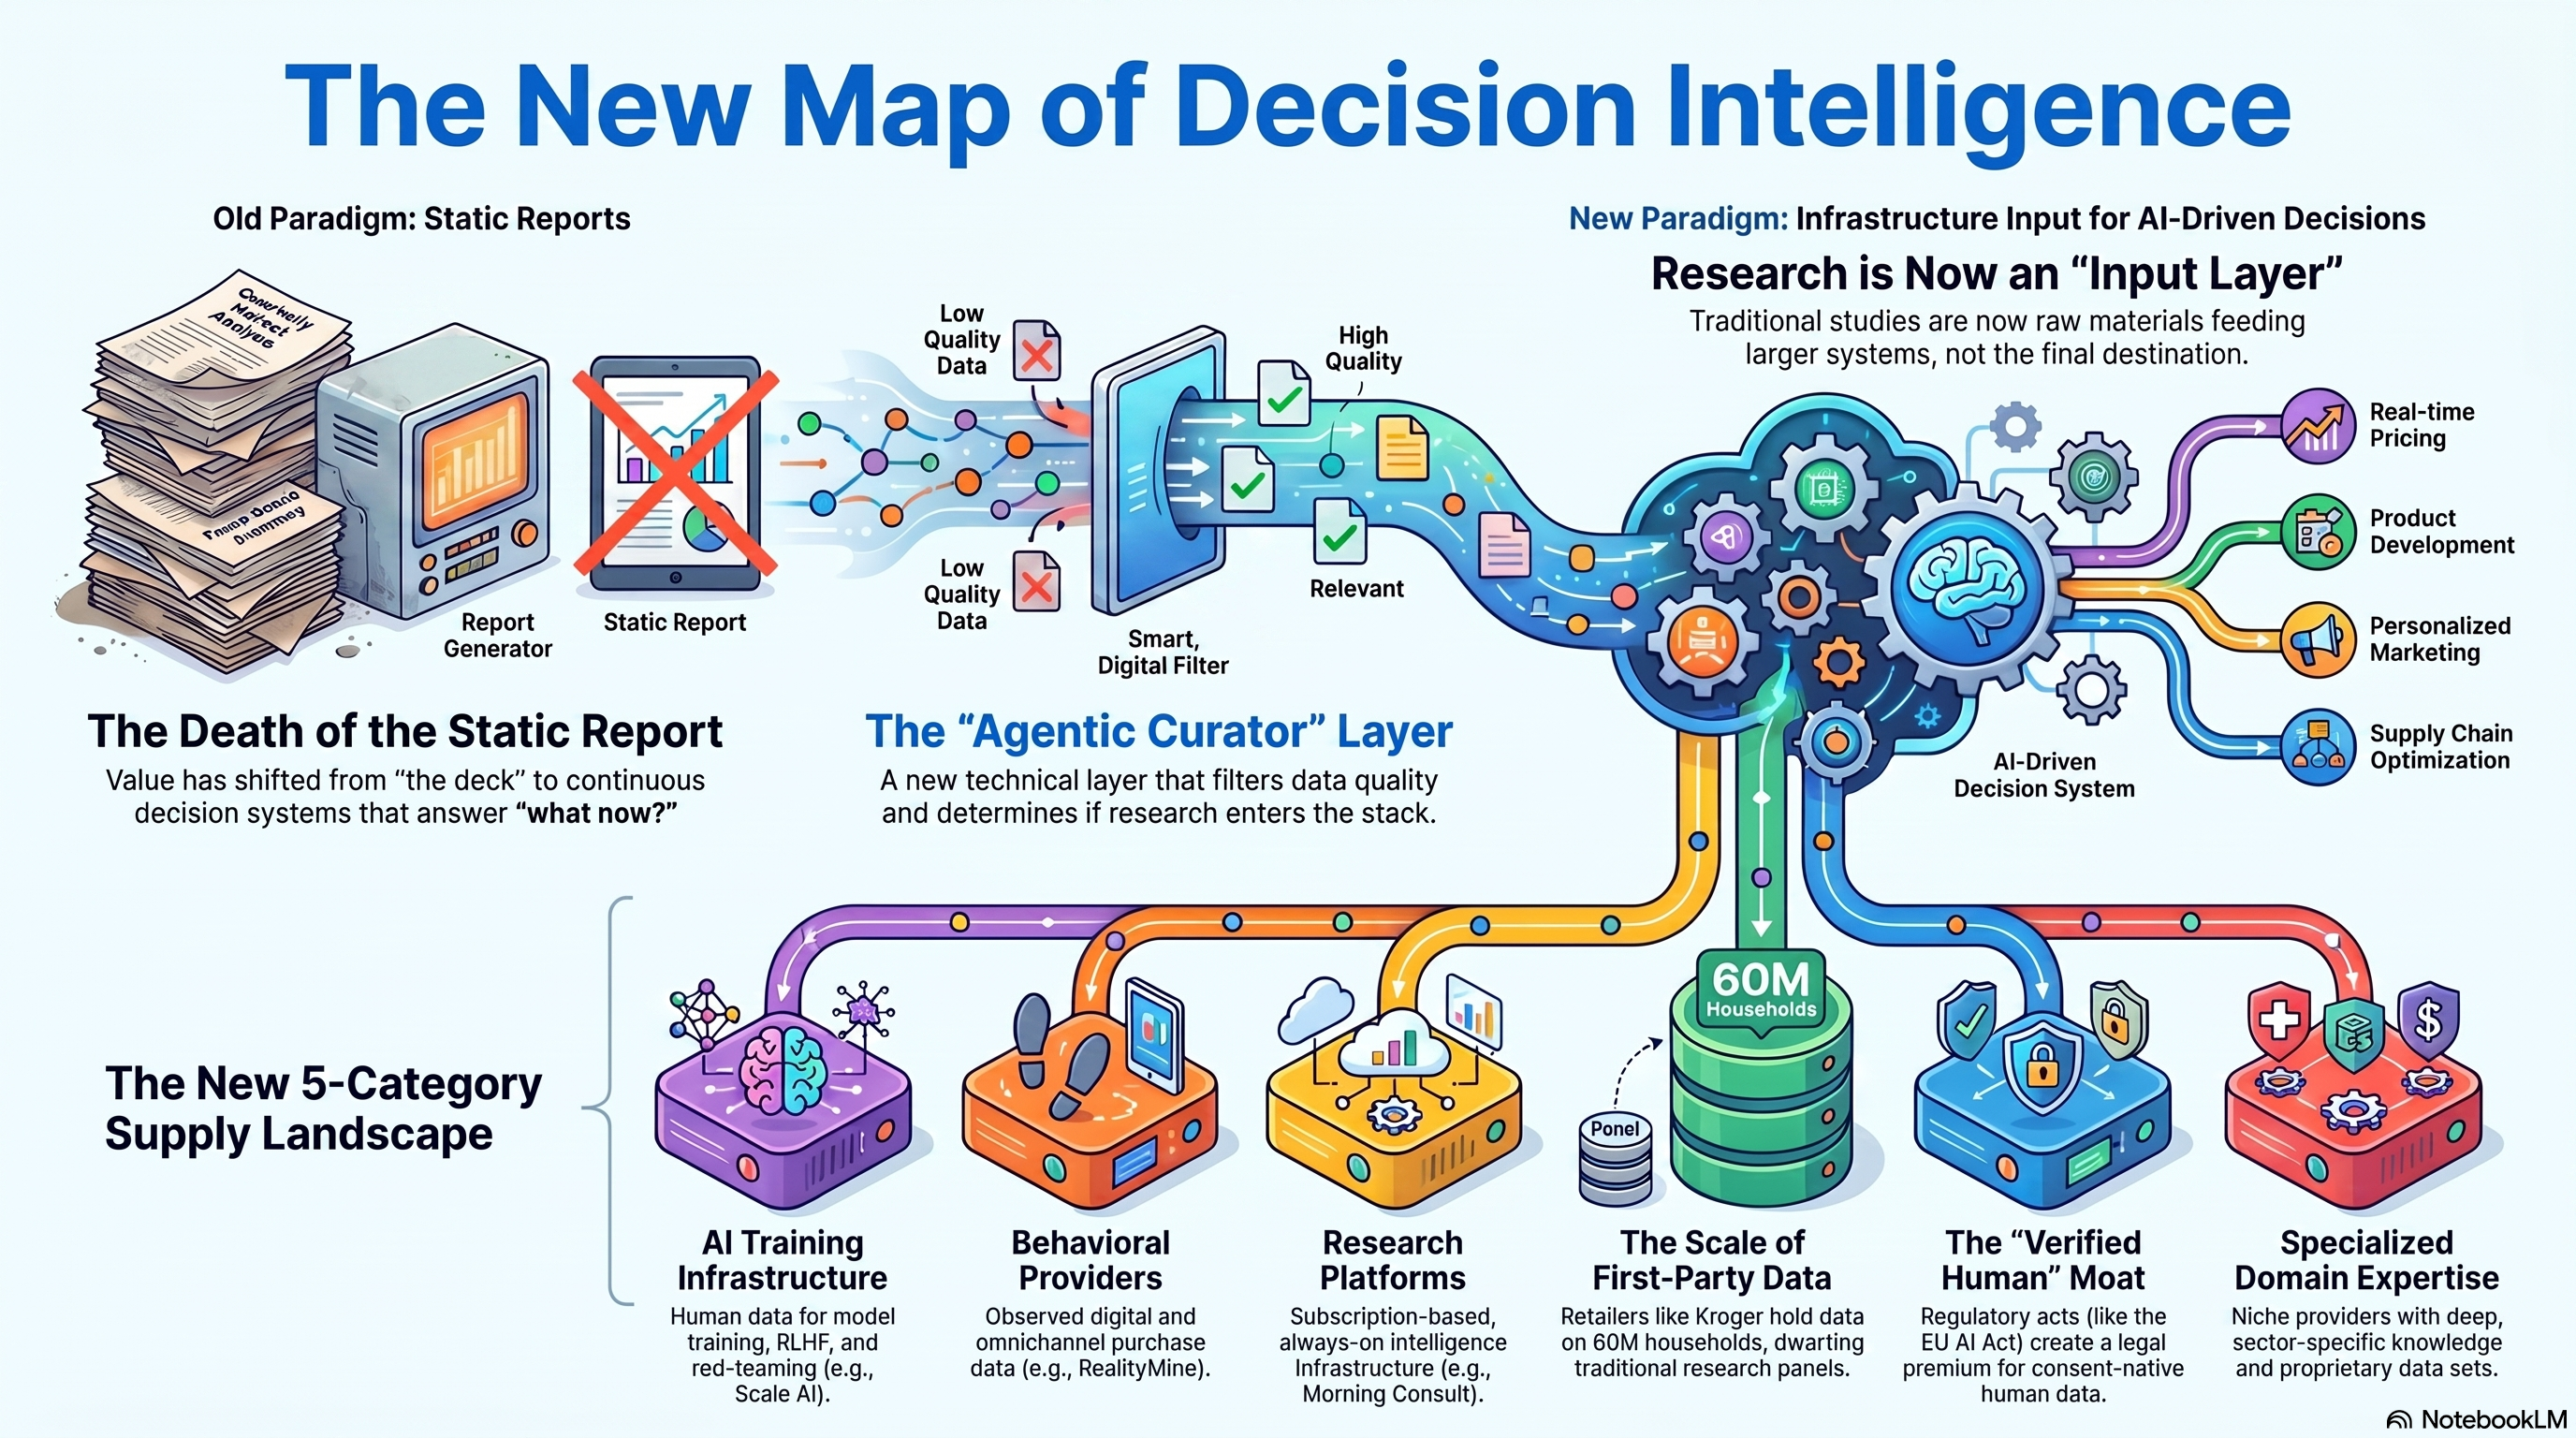
Over the past several months, we have been tracking a set of structural forces reshaping the insights and analytics industry from the outside in. We have written about the data infrastructure layer being rebuilt around verified human data. We have written about how private equity is reconceiving research businesses as infrastructure platforms rather than service firms. We have written about what the Qualtrics debt drama signals about how capital markets are re-pricing the category.
This post is a different kind of zoom out.
Each of those stories is real. But they are episodes in a larger structural shift that we have not yet named directly. So let’s name it.
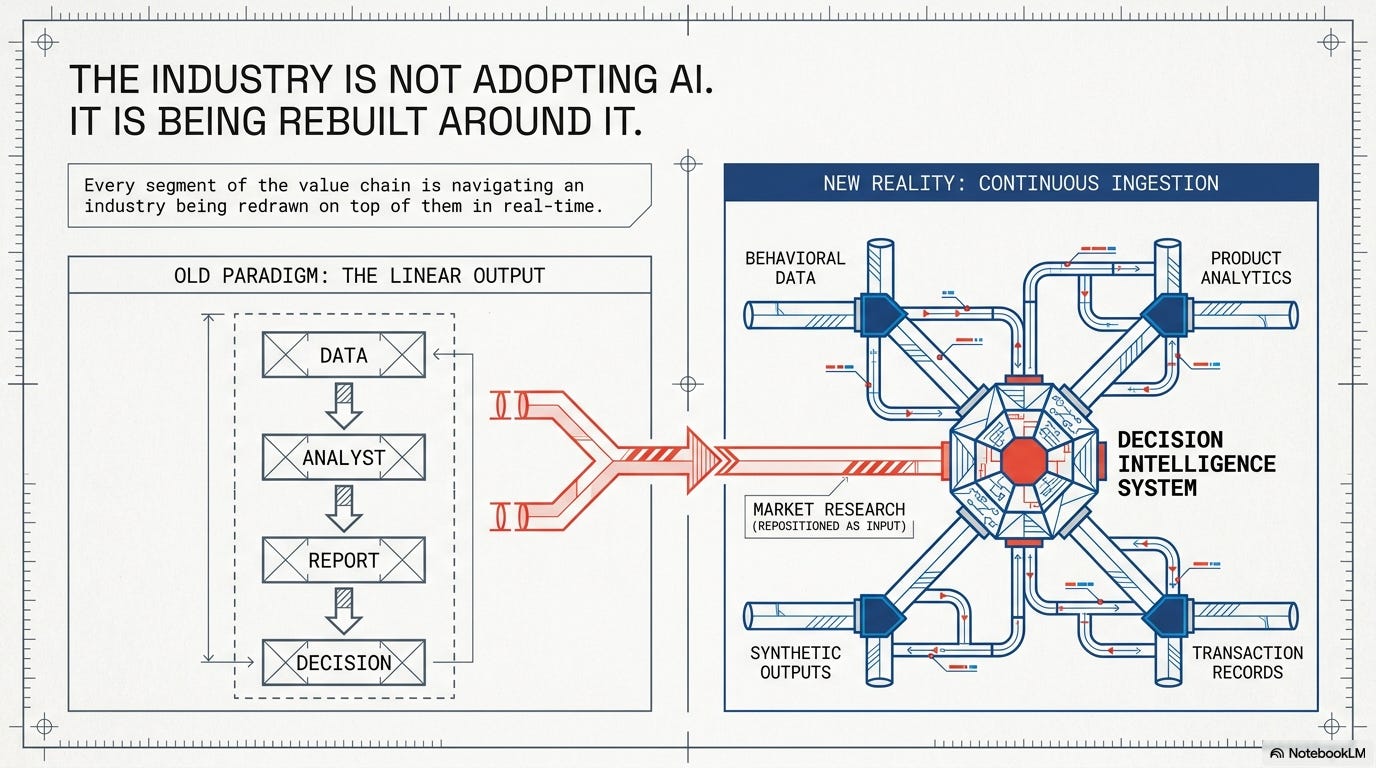
The insights and analytics industry is not merely adopting AI. It is being reorganized around a fundamentally different model of how enterprise decisions get made — and who or what makes them. Every segment of the value chain is affected. Every role is affected. The suppliers, the buyers, the infrastructure providers, the technology platforms, and the professionals who work inside all of them are navigating an industry that is being redrawn on top of them in real time.
This post is about the structure of what is emerging. The new constituencies. The new dynamics. The new map.
The Old Model Is Not Declining. It Has Become the Input Layer.
Let’s start with the most important thing to understand about the current transition, because it is the thing that is most frequently misframed.
Traditional market research — the custom survey, the focus group, the ad-hoc quant study commissioned to answer a specific question — is not disappearing. It is being repositioned. Specifically, it is being repositioned from the output layer of the intelligence value chain to the input layer of a much larger system.
In the old model, the research deliverable was the product. The deck, the topline, the key findings, the strategic implications. The decision lived downstream of the research, in the judgment of the person who read it and acted on it. Research was the last stop on the intelligence journey.
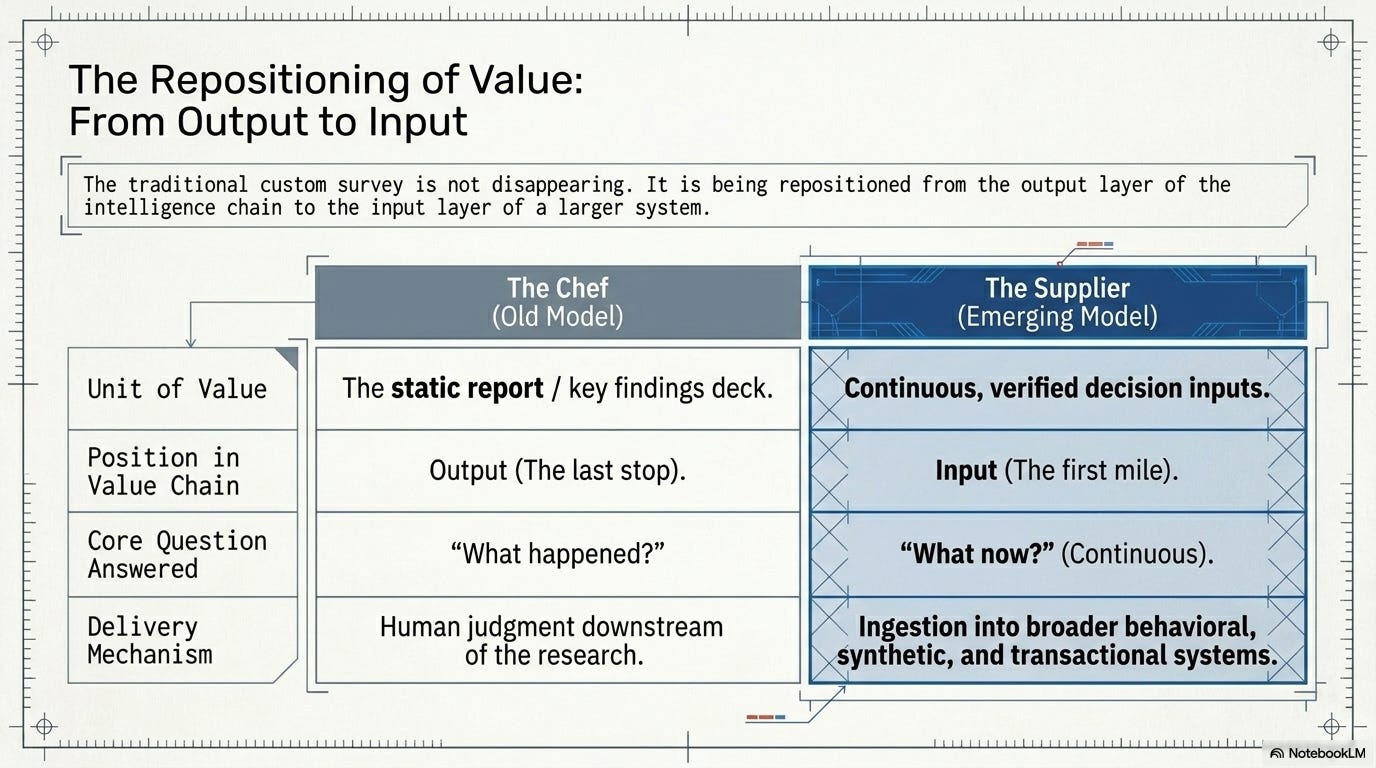
In the emerging model, that same research — the survey, the qual, the concept test, the brand tracker — is an input to a system that also ingests behavioral data, transaction records, product analytics, social signals, experience data, and a growing array of synthetic data outputs. The intelligence product is not the research. It is the decision system the research feeds.
This is not a subtle distinction. It is the difference between being the chef and being a supplier to the kitchen.
The unit of value has changed. Companies are data-rich and decision-poor, and the static report has not merely declined in relevance — it has, for practical purposes, ceased to function as the primary mechanism of enterprise intelligence. The Monday-morning question — what now? — is consistently unanswered by the old model. The new model is built to answer it continuously.
The Stack Has Seven Layers. Most Buyers Are Navigating Blind.
Here is where the structural complexity of the current transition becomes genuinely difficult for enterprise buyers to navigate.
The competitive landscape of the insights and analytics supply side has fractured into at least seven functionally distinct categories. Not segments. Not subcategories. Categories — with different economic models, different technical architectures, different data governance postures, and, increasingly, different strategic ambitions.
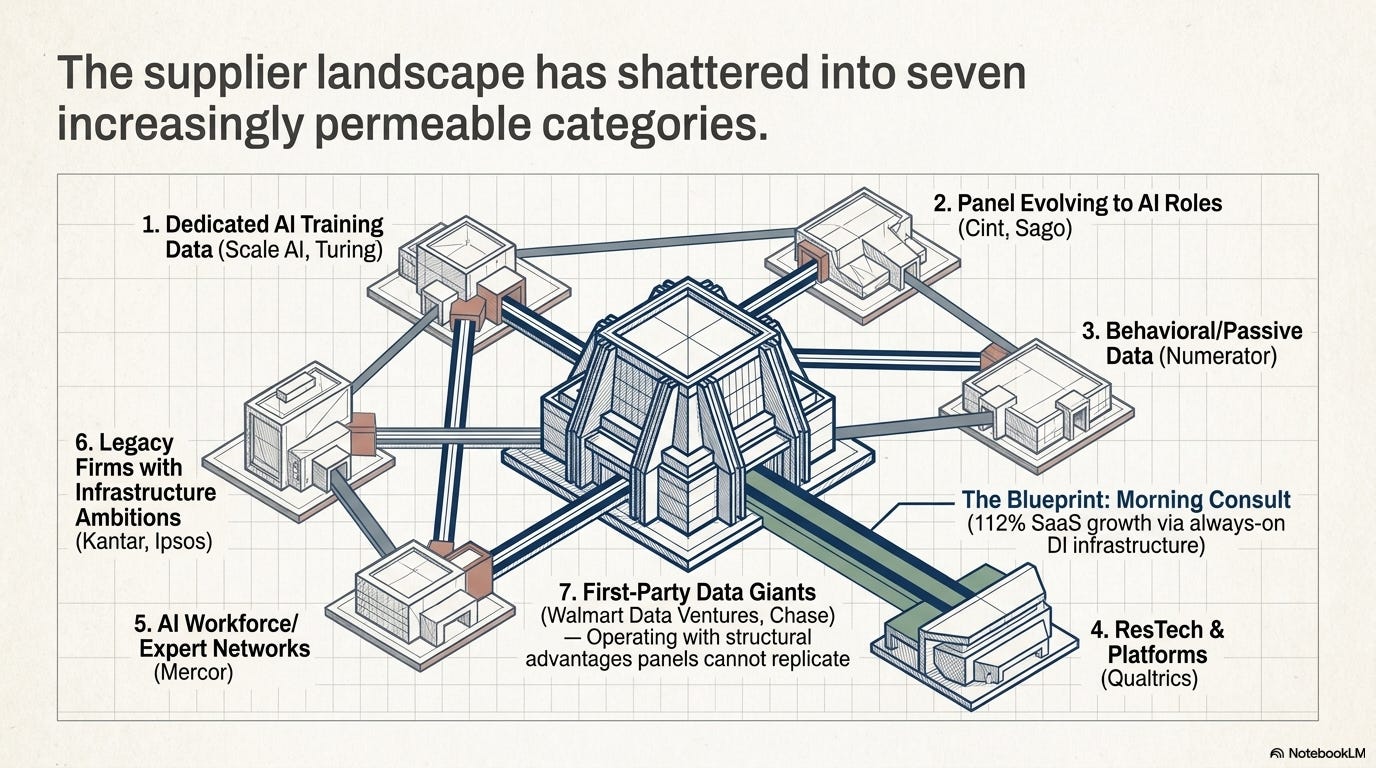
1. AI training data and human annotation infrastructure. Platforms like Scale AI, Prolific, and Toloka/Tendem built explicitly for the AI economy — human data for model training, RLHF, evaluation, red-teaming, and adversarial testing. Scale AI’s acquisition by Meta is the clearest capital markets signal of what the AI ecosystem is willing to pay for verified human data infrastructure.
2. Panel and sample infrastructure evolving toward AI data roles. The traditional sampling and respondent-access layer — Cint, Dynata, PureSpectrum, Prodege — is at a strategic inflection point, with some players explicitly repositioning as AI training data sources and hybrid pipelines while others remain anchored to project-based survey access.
3. Behavioral and passive data providers. Companies like Qrious Insight, Numerator, and RealityMine supplying observed behavioral signals — digital metering, omnichannel purchase data, device-level tracking — as ground truth for AI systems that need to know what people do, not just what they say.
4. Research intelligence platforms and data marketplaces. Morning Consult, GWI, YouGov, NIQ, and Qualtrics at varying positions along the spectrum from traditional research firm to always-on decision intelligence platform. Morning Consult’s execution is the clearest proof point of what the transition looks like in practice: 30,000 daily surveys across 100 markets, repackaged as subscription intelligence infrastructure, delivering 112% year-over-year SaaS line growth. That is survey data converted to infrastructure economics.
5. Expert talent networks and AI workforce platforms. An emerging category of specialized human-in-the-loop platforms providing expert human judgment at scale — for validation, calibration, edge-case adjudication, and the irreducible human functions that AI systems cannot perform on themselves.
6. Established research firms with declared infrastructure ambitions. Kantar, Ipsos, and their peers attempting to navigate the transition from legacy custom research models to some version of the data and platform economics that the new category leaders are demonstrating. This is the category with the widest range of outcomes ahead of it.
7. Retailer, financial services, and platform first-party data providers. This is the most consequential and least understood entry from outside the traditional industry. Walmart Data Ventures/Scintilla, 84.51°/Kroger, PayPal Advertising, Chase Media Solutions, Visa Intelligent Commerce — these companies are entering the enterprise intelligence market with structural advantages that traditional research firms cannot compete with directly: transaction-verified behavioral data at consumer scales no panel can replicate, continuous refresh at operational cadence, and embedded consent from commercial relationships that predate AI.
84.51°/Kroger holds purchase behavior data from approximately 60 million U.S. households. PayPal analyzes close to half a trillion dollars of transaction data with AI. No research panel is going to out-scale that on transactional behavioral ground truth. The question is not how the research industry competes with those assets — it cannot — but how it occupies the intelligence layer those assets structurally cannot provide.
The buyer’s problem is real and specific. A VP of Consumer Insights or a VP of Analytics trying to build a modern decision intelligence capability in 2026 needs to navigate all seven of these categories, understand what each can and cannot do, know how different data types interact and at what quality levels, govern AI and synthetic data usage in ways that satisfy both internal risk standards and emerging regulatory requirements, and assemble all of it into a system that actually improves decisions rather than just accumulating data costs. No playbook for doing that currently exists.
The Operating Model Changed Before Anyone Announced It
One of the more striking findings from the latest wave of practitioner research is this: the operating model of the insights function changed before most leadership teams realized they had a decision to make.
The data shows two very different realities running in parallel inside enterprise organizations.
Analytics and data science professionals — the segment most closely tied to the emerging decision intelligence model — are at or near all-time highs on project budgets, staffing, technology spend, and outsourcing. The operating model is expanding.
Research and consumer insights professionals — the segment most tightly associated with the traditional model — are experiencing flat-to-declining project spend, the first negative staffing reading in the tracked period, and contraction in outsourcing. The operating model is being quietly redefined.
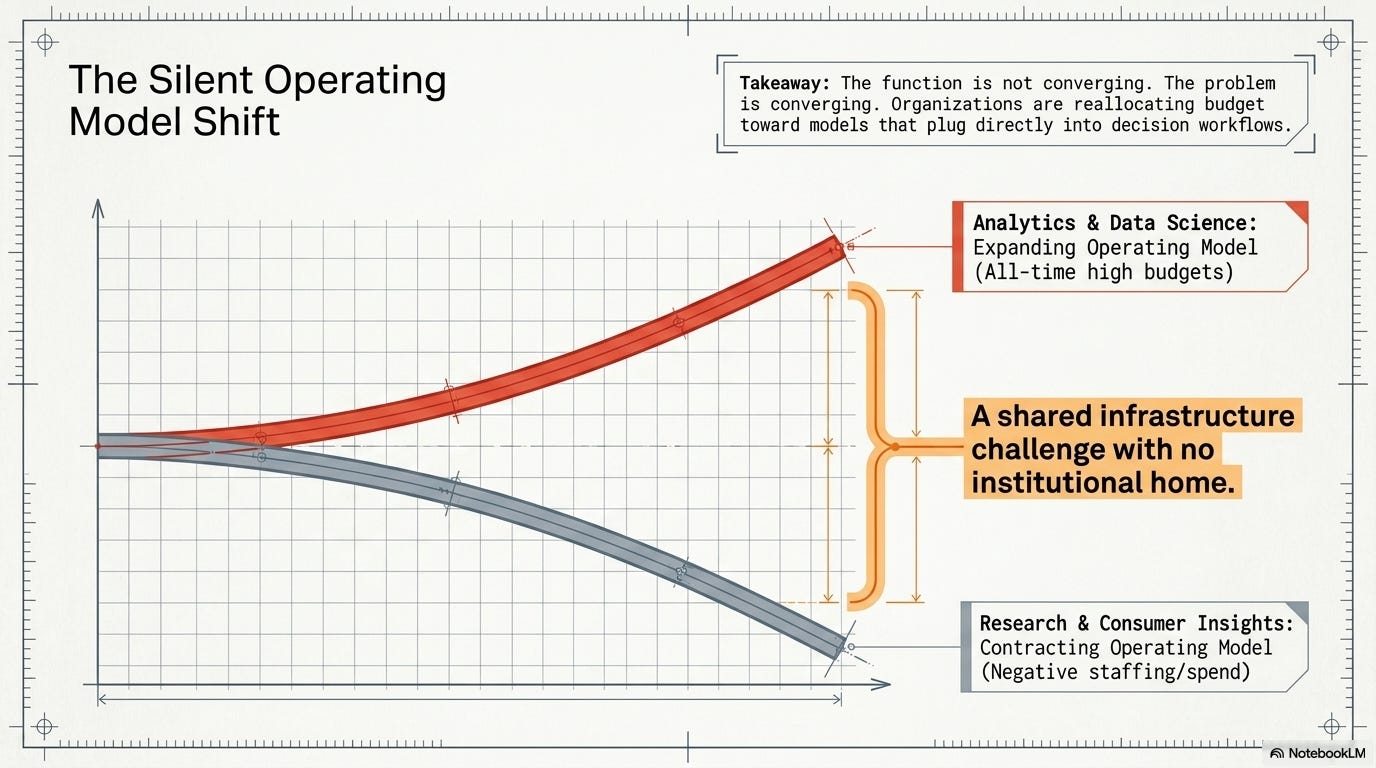
This is not two job titles diverging in a spreadsheet. It is evidence that enterprise organizations have begun quietly reallocating the work — and the budget — of understanding their customers toward the operating model that plugs directly into decision workflows, and away from the model that produces discrete deliverables for downstream judgment.
The function is not converging. The problem is converging. A VP of Consumer Insights, a VP of Analytics, and a Head of Product Experimentation at the same large organization all face a version of the same structural challenge right now: how to evaluate, govern, and integrate a supply landscape with seven categories, a synthetic-real data spectrum with specific use-case constraints and quality requirements, behavioral data feeds requiring different governance logic than survey data, and an agentic AI layer beginning to intermediate how intelligence is queried and delivered.
The professionals who face that challenge are in different departments, report through different chains of command, and have different technical backgrounds. But the infrastructure challenge is shared. And currently, there is no institutional home for it.
The Architecture Underneath Everything
Understanding the new model requires understanding the technical architecture now emerging as the standard enterprise decision intelligence stack.
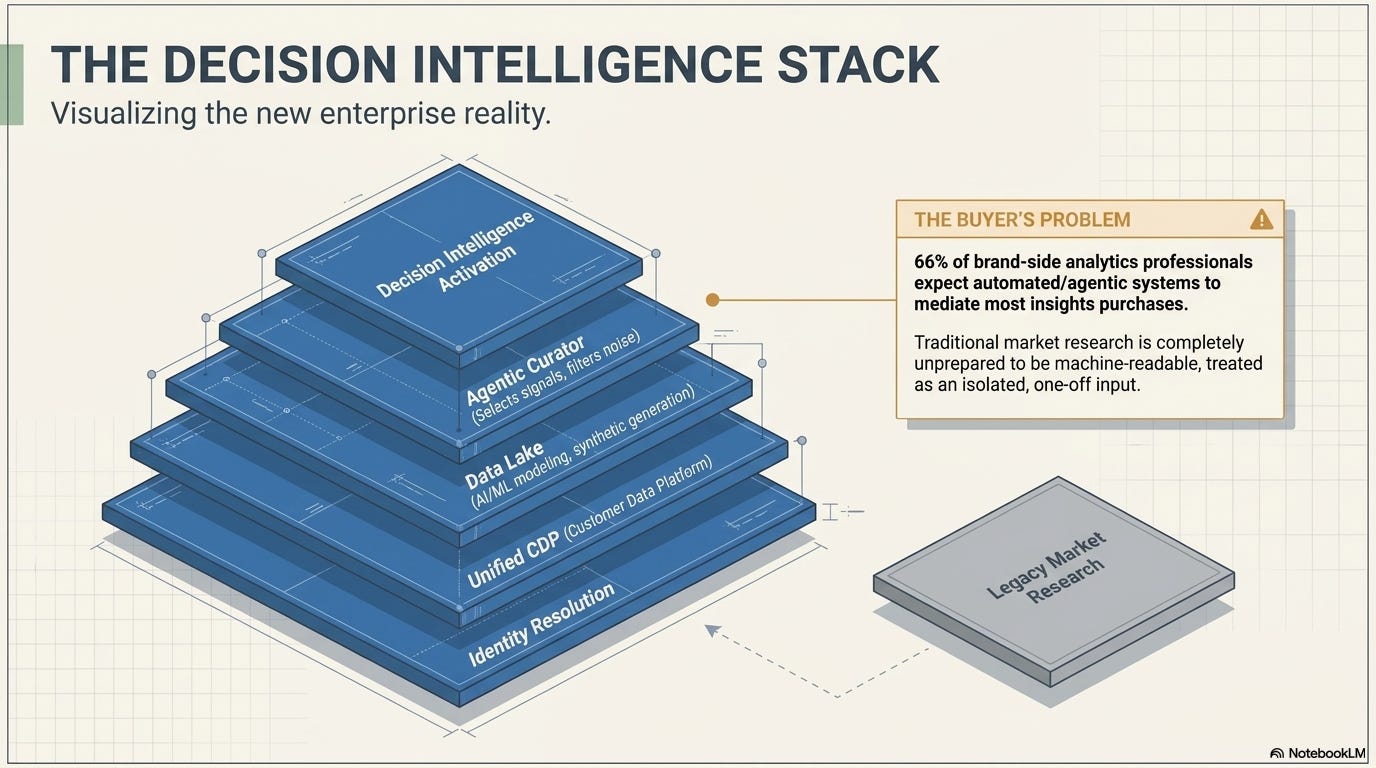
At the base layer is identity resolution — establishing a common key linking the same individual across fragmented data sources: CRM, loyalty, transactions, web analytics, email, campaign history. Without this, every data silo sees a fragment of the customer. With it, the rest of the stack can function.
On top of identity resolution sits the Customer Data Platform — a unified, real-time customer profile layer that knows who the customer is at any given moment and can push the appropriate action to the appropriate channel. The CDP is the operational brain: it receives model outputs, manages segmentation, and activates across channels.
The data lake/warehouse layer functions as the memory and learning system — historical data storage, AI/ML model training, synthetic data generation, scenario simulation, and propensity modeling. Where the CDP knows who, the data lake knows what patterns exist in history.
The fourth layer, and the one that will matter most for the insights industry, is the Agentic Curator Layer — a continuously running system that decides which signals are relevant to any given decision, removes noise and corrupt data, detects coverage gaps, applies business context that pure statistical pipelines cannot, assembles curated input profiles for models, and monitors whether predictions matched actual outcomes. This is the layer that creates the feedback loop making the system self-improving. It is also the layer that determines whether traditional research data enters the stack at all — and in what form, at what quality tier, with what provenance documentation.
Traditional market research, in its current form, is essentially absent from this stack. It is either treated as a one-time input with no refresh cycle, or not integrated at all. That is the architectural version of being repositioned as the input layer: you matter, but only if you can enter the pipeline in a form the rest of the stack can consume.
What that means practically is that the question “which research firm should we use?” is increasingly a downstream question. The upstream question — being answered by CDPs, data governance teams, and AI platform vendors, not research leaders — is “what data quality tier do we need for this decision type, and what provenance documentation does our AI risk posture require?” Research that cannot answer that question in its own metadata gets filtered out.
Three Positions Are Emerging. Most Firms Have Not Chosen.
Against this restructuring, the strategic landscape for insights and analytics firms has resolved into three viable positions. Most companies in the category are currently occupying none of them clearly.
Position A: Verified Human Data Infrastructure. Consent-native, identity-anchored, continuously refreshed, API-accessible human data — the calibration layer that AI systems need and cannot self-supply. The regulatory environment is accelerating this position’s defensibility: the EU AI Act, which becomes fully applicable in August 2026, requires that training data for high-risk AI systems be documented, representative, and free of errors, with provenance and bias assessment. That is a legal moat for premium human data suppliers who have always operated with opt-in consent architecture.
Position B: Decision Intelligence Platform. Always-on, natural language-accessible decision intelligence embedded in enterprise workflows — the model Morning Consult is executing most explicitly, and that Qualtrics’ new CEO described at X4 as the pivot from “system of insight” to “system of decision.” The companies that win this position will be those whose data is already inside enterprise AI workflows, whose APIs are already called by the Agentic Curator Layer, and whose content is already trusted as a calibration source by enterprise analytics teams building the stack.
Position C: AI Data Exchange Marketplace. Neutral infrastructure through which data owners license assets to AI consumers — the LiveRamp model, now explicitly expanded to AI training data licensing. This position is available to platforms that have both distribution reach and governance credibility.
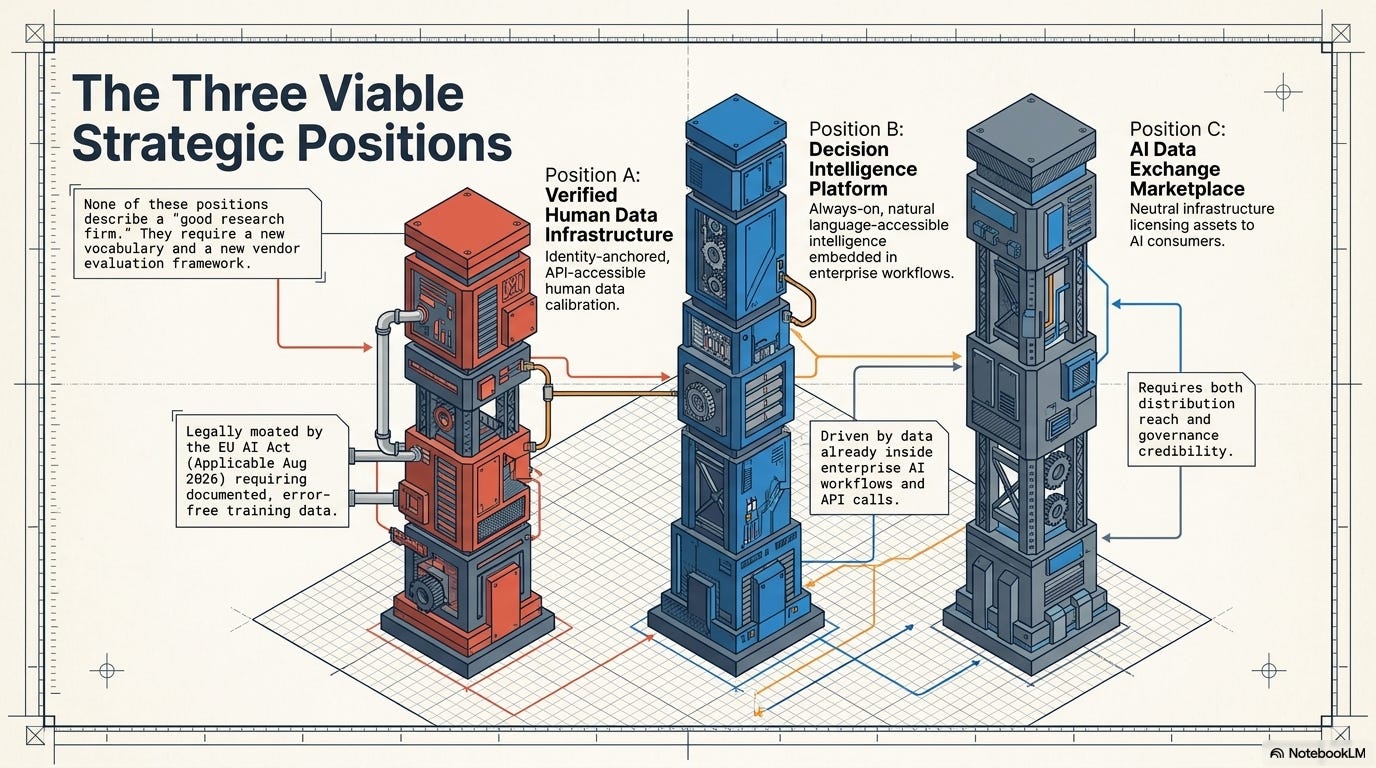
The important observation about all three positions is that none of them describes “a good research firm.” A buyer trying to navigate toward any of them needs a different vocabulary, a different vendor evaluation framework, and a different understanding of what questions to ask than the traditional RFP process provides. The industry is generating new supply categories faster than buyers are developing the navigation tools to evaluate them.
What This Means for Every Participant in the Value Chain
The structural transition described here is not a threat to one segment of the industry. It reshapes the position of every participant.
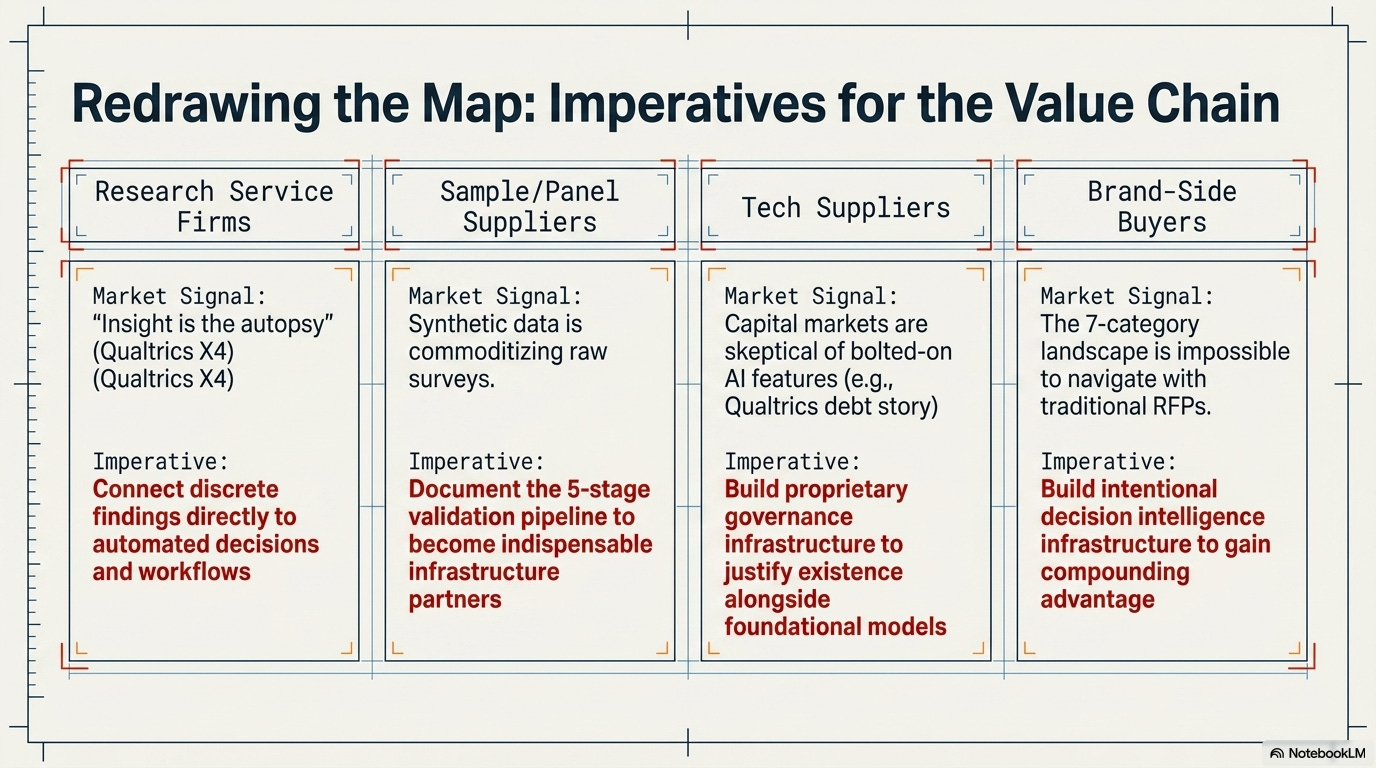
For research service firms, the “insight is the autopsy” framing that Qualtrics’ new CEO used at X4 is not a competitor’s tagline — it is a market signal. The category leader is publicly declaring that insight alone is an insufficient deliverable. Service firms still selling discrete findings as the primary product need to respond with concrete mechanisms connecting their work to decisions, workflows, and measurable outcomes.
For sample and panel suppliers, the synthetic data governance questions that major analyst firms are now raising publicly are an opening, not a threat. The five validation requirements now being demanded — data sourcing and quality, comparative testing against first-party data, conclusion similarity testing, hallucination checks, and bias mitigation — are questions that well-governed, consent-native panel suppliers are structurally positioned to answer. Those who can document these answers will be positioned as trusted infrastructure partners. Those who cannot will be commoditized by the very synthetic platforms they are told to complement.
For research technology suppliers, the question capital markets are asking is not “does this company have AI features?” It is “does this company have a defensible reason to exist in a world where the intelligence layer is increasingly provided by OpenAI, Anthropic, or Google?” Platforms that can answer that question with proprietary data, governance infrastructure, or deep domain integration will attract capital. Those that cannot will face the same investor skepticism that surfaced in the Qualtrics debt story.
For brand-side buyers, the structural challenge is real and the navigation gap is genuine. The seven-category supply landscape, the synthetic-real quality spectrum, the agentic architecture beginning to intermediate procurement — none of this is addressed by existing infrastructure built for a different version of the industry. The operating model transition is happening whether or not the buyer is actively managing it. Organizations building intentional decision intelligence infrastructure will have a compounding advantage over those running the old model with AI features bolted on.
For the entire supply chain, the abstraction risk deserves the most honest attention. The most dangerous scenario is not that AI replaces research. The more likely danger is that the industry gets abstracted — layer by layer, workflow by workflow — until traditional suppliers are less visible in the decisions that matter. The client’s AI platform absorbs the dashboard. The synthetic tool absorbs concept testing. The CRM absorbs customer understanding. The product analytics platform absorbs user research. None of those substitutions happen all at once. But each one makes a traditional research supplier marginally less essential to the decision workflow. Abstractions compound.
The Window Is Open. It Is Not Open Indefinitely.
The structural positions being staked out right now — in data infrastructure, in workflow embedding, in governance and provenance architecture, in the agentic stack — will become increasingly difficult to displace once established.
Infrastructure compounds. A panel supplier that achieves API-level embedding in the Agentic Curator Layers of major enterprise AI platforms in 2026 will be structurally advantaged relative to one that achieves it in 2028. A research intelligence platform that becomes the trusted calibration source for enterprise AI systems in 2026 will be cited, referenced, and called by default in ways that a later entrant will have to earn against an established baseline.
The competitive dynamics we have been tracking in this newsletter — the seven-category restructuring, the data infrastructure repricing, the private equity reclassification, the Qualtrics canary signal — are all episodes in the same underlying story. The industry is being redrawn. Every participant is navigating a map that is being drawn in real time.
The firms that develop the clearest map fastest will have an enormous advantage. Not just a competitive advantage. A structural one.
The window is open. The question is who uses it.
This post draws on analysis from our ongoing coverage of the decision intelligence infrastructure build-out, the GRIT 2026 Business Outlook research, the IIV Human Data Infrastructure report, and primary source data from the competitive landscape. We invest in AI and analytics startups across the USA and UK focused on data infrastructure, research technology, and AI-native insight platforms. If you found this useful, subscribe for free to receive these analyses directly. Related reading: The Data Infrastructure Layer Is Being Rebuilt · The Next Roll-Up Is Not a Roll-Up · The Qualtrics Canary