

Note: We are experimenting with various ways to make our content more engaging and impactful using AI tools like Notebook LM. You’ll notice a variety of graphics in this report, but we also have adapted the content to a video as a “tldr” option. Let us know what you think of both?
Here is the video summary of the post first.
We’re continuing our deep dive into specific sectors of the insights & analytics market that we started in The Future of Professional Services Is a Warning Shot for Market Research and continued in The Data Infrastructure Layer Is Being Rebuilt — Is the Insights Industry Sleeping Through It?, now focusing on the hot topic of the synthetic sample market.
Synthetic sample is moving from curiosity to category. The phrase now covers AI personas, synthetic respondents, digital twins, simulated audiences, statistical augmentation, and multi-agent behavioral systems. That breadth is useful commercially, but it is dangerous analytically. It makes the market sound more coherent than it is.
The insights industry should resist the easy framing. This is not simply a story about AI replacing survey respondents. Some low-risk research tasks will be compressed, automated, or repriced. Some fieldwork will be avoided. Some synthetic outputs will be good enough for fast iteration. But the larger shift is not replacement. It is the rebuilding of the decision-input layer around a new question: which human data is valuable enough to become the ground truth for machines?
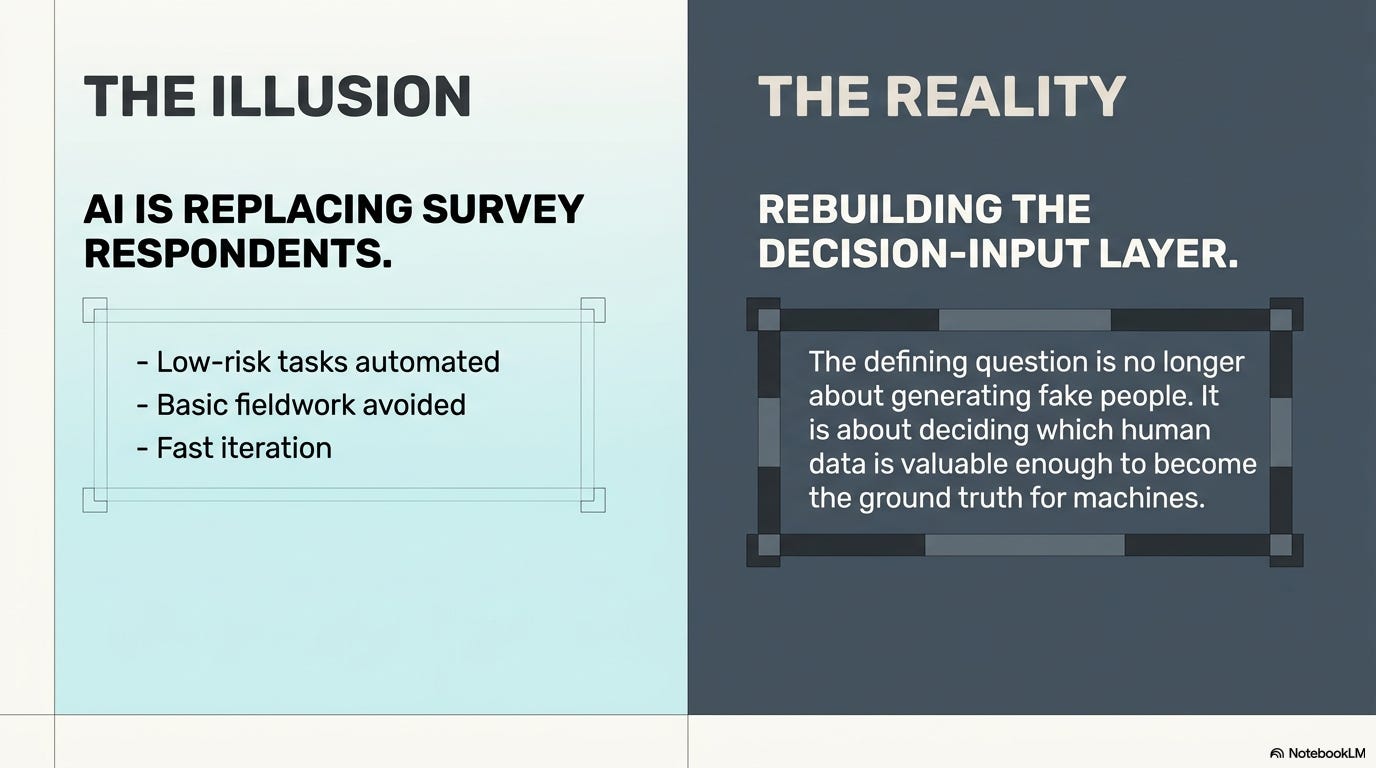
That is the real market.
The demand is real. The category is confused.
Note: We’re going to mention a few companies as we dive into this as examples in each category: this is just a representative sampling of players, not a census and no offense is meant to any supplier if you were not mentioned, and no implied endorsement is meant for any we do.
Clients want faster answers, lower costs, fewer bad completes, and less dependence on brittle fieldwork. They are also under pressure to put insight closer to product, marketing, sales, CX, media, innovation, and strategy workflows. Synthetic sample appears to answer all of that: no recruiting delay, no incentive cost, no panel fraud, no respondent fatigue, no waiting.
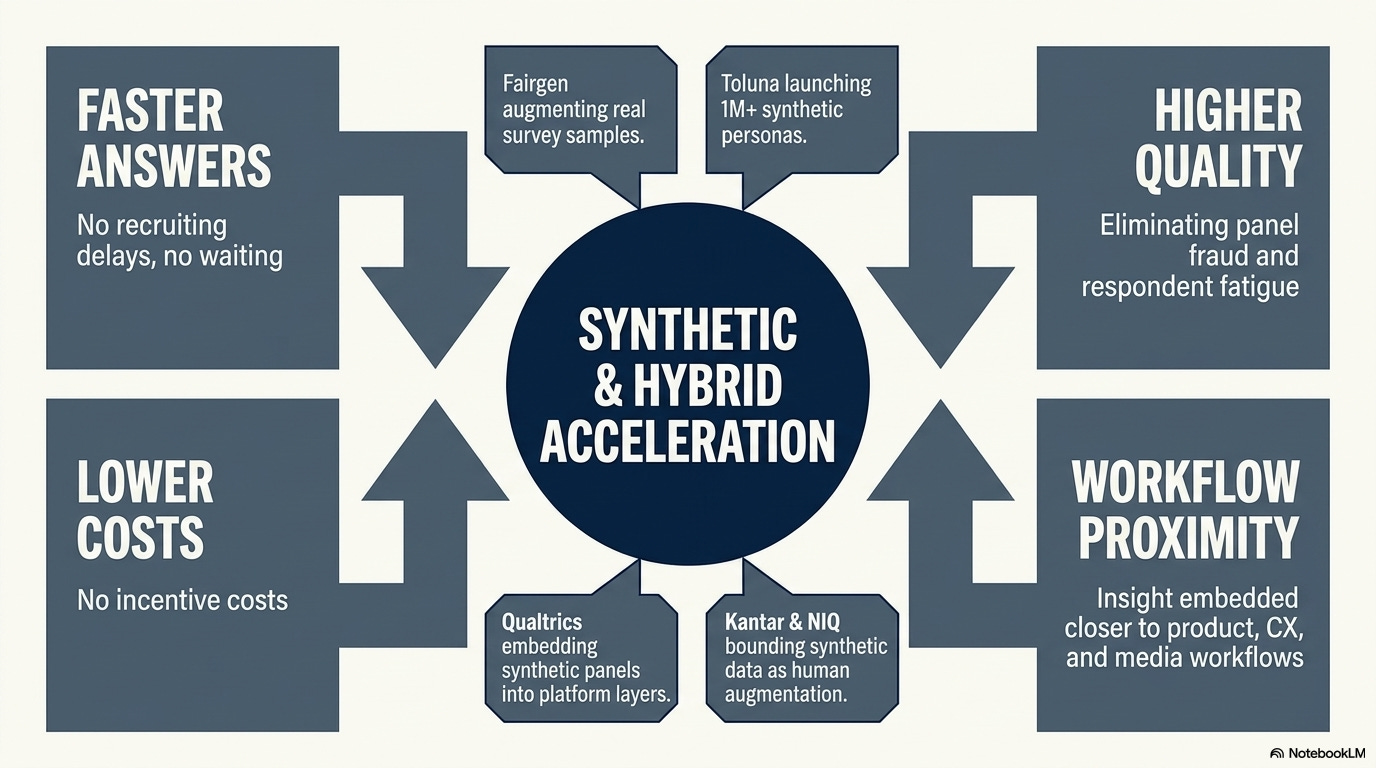
That is why the market is forming so quickly. Fairgen is using AI to augment real survey samples rather than simply inventing respondents (TechCrunch). Qualtrics is embedding synthetic panels into the survey platform layer (Qualtrics). Toluna has announced more than one million synthetic personas tied to its panel infrastructure (Yahoo Finance). Kantar and NIQ are both framing synthetic data as useful, but bounded, augmentation of human research rather than as a magic substitute (Kantar, NIQ).
At the same time, a different class of companies is aiming higher than “synthetic survey respondent.” Simile is positioning around behavioral simulation and reportedly raised a $100 million Series A to help organizations predict human behavior (Bloomberg, TechFundingNews). Aaru is using agent-based simulation for population and decision modeling, including a public EY wealth and asset-management use case (EY). Electric Twin is commercializing synthetic audiences with The Times and News UK, which matters because it turns simulation into a media-planning product rather than a research demo (Research Live).
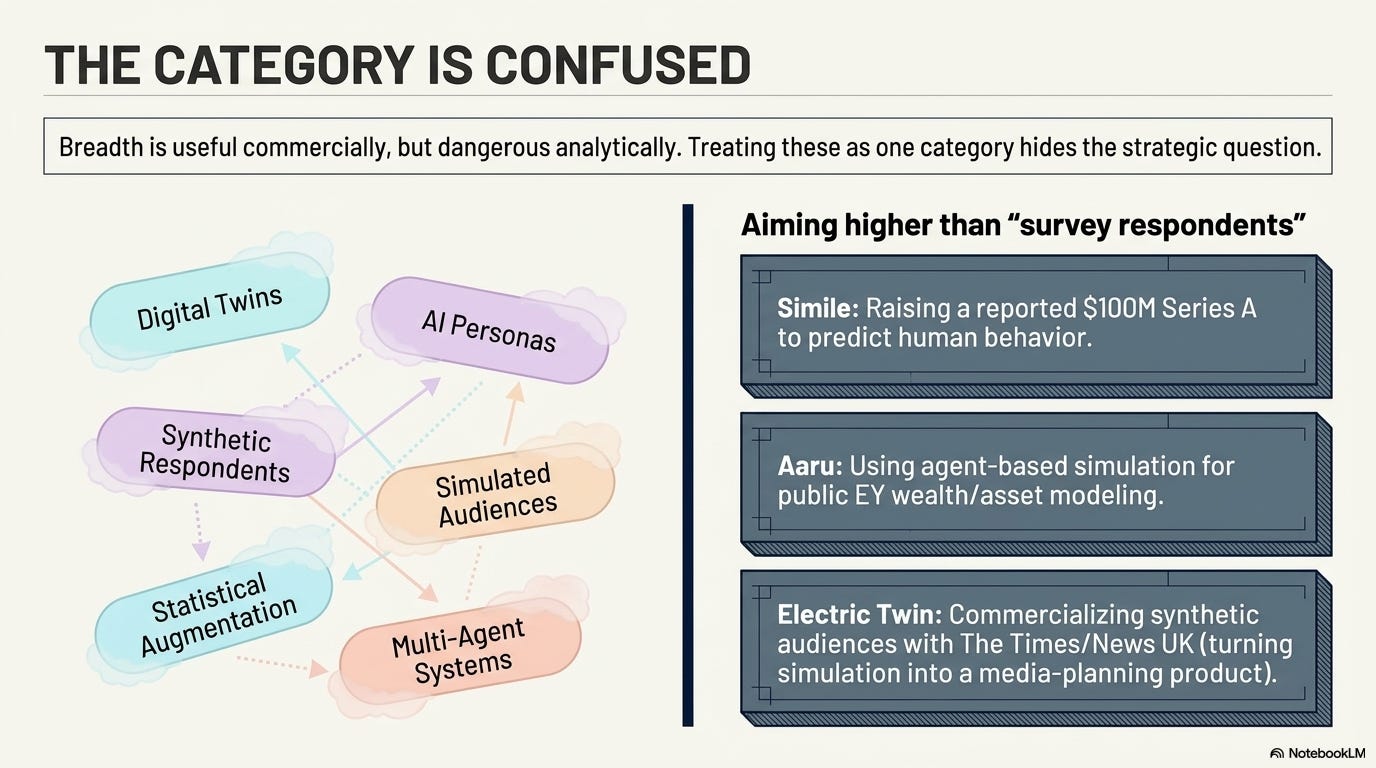
Those are not the same business. Treating them as one category hides the strategic question.
A new synthetic and hybrid data stack is forming
The market is sorting into at least six layers.
Statistical augmentation starts with real human data and uses models to fill sparse cells, improve subgroup coverage, or extend survey datasets. This is the least theatrical version of the market, but potentially one of the most defensible because it begins with actual human evidence.
AI personas and synthetic respondents create simulated consumers, users, voters, professionals, or buyers who can answer questions, react to concepts, or join simulated qualitative exercises. This layer is useful for ideation, question testing, scenario exploration, and early-stage discovery. It is also where the most commoditization risk sits, because generic LLM-based personas are easy to create and difficult to defend.
Digital twins attempt to make real people, respondent groups, or audience segments re-queryable. Brox, Panoplai, Xpolls.ai, Toluna HarmonAIze, and Yabble/YouGov Virtual Audiences all point toward the same idea: if a company already has rich human data, it may be able to create a persistent synthetic representation that can be queried repeatedly (Brox via VentureBeat, Panoplai ESOMAR, Yabble).
Multi-agent simulation tries to model behavior, interaction, persuasion, contagion, adoption, or collective response. This is closer to decision simulation than sample replacement. It may ultimately compete less with survey platforms and more with strategy consulting, media planning, product forecasting, policy modeling, and enterprise decision systems.
Synthetic audience and media-planning products are becoming commercially real because advertisers and publishers already buy audiences, scenarios, and predicted response. Electric Twin’s News UK partnership and BluePill.ai’s brand and media positioning are examples of synthetic approaches moving into buyer workflows that already accept modeled planning inputs (Research Live, GeekWire).
Grounding and validation infrastructure may be the most valuable layer. Quilt.ai, Emporia, Realeyes, panel companies, transactional data owners, passive-behavior platforms, and major research incumbents may not all look like synthetic sample vendors, but they own or access the real human signals synthetic systems need in order to be trusted (Quilt.ai, MRWeb on Emporia, Realeyes AdvertEyes).
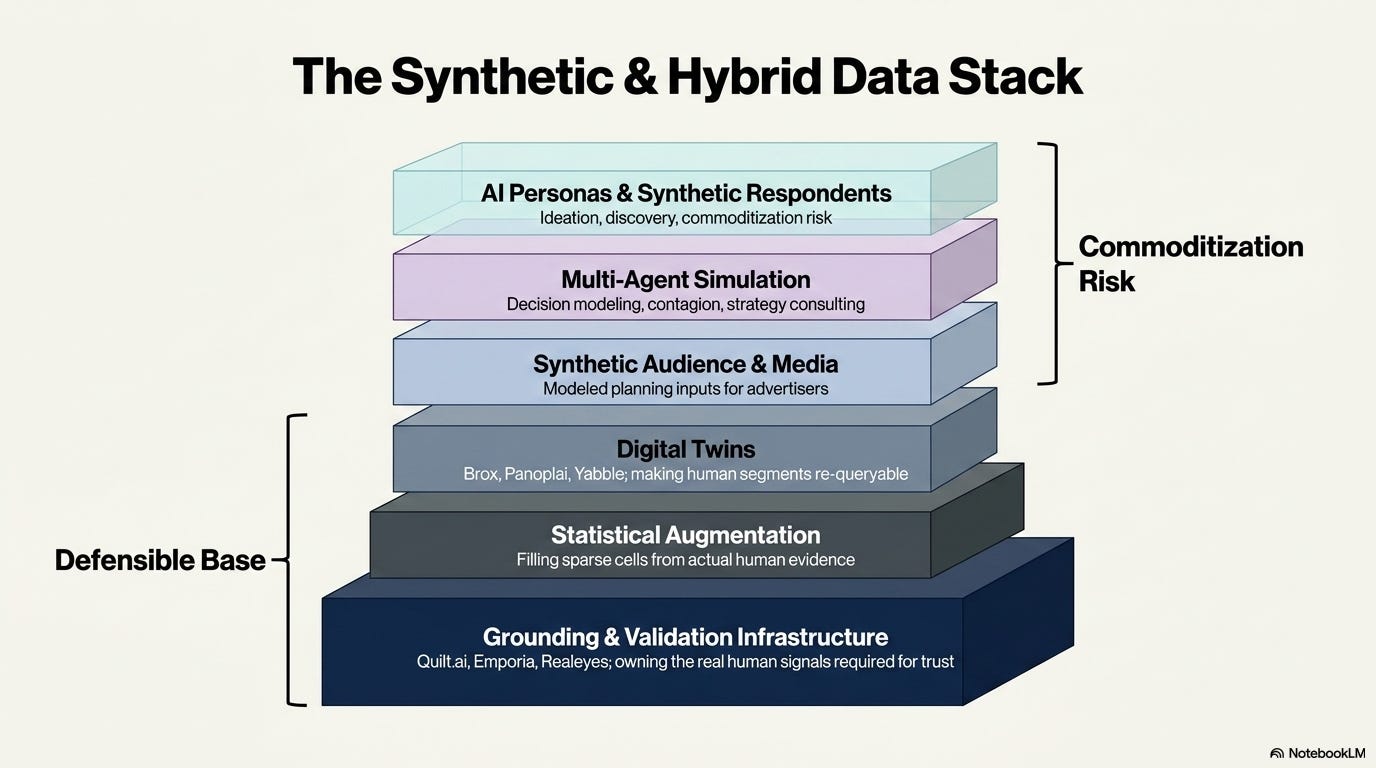
The important point is not that one layer wins and the others lose. The important point is that the market is moving away from “generate respondents” and toward “assemble decision-grade evidence.”
The market is moving from speed to trust
The first pitch for synthetic sample is speed. The durable pitch will be trust.
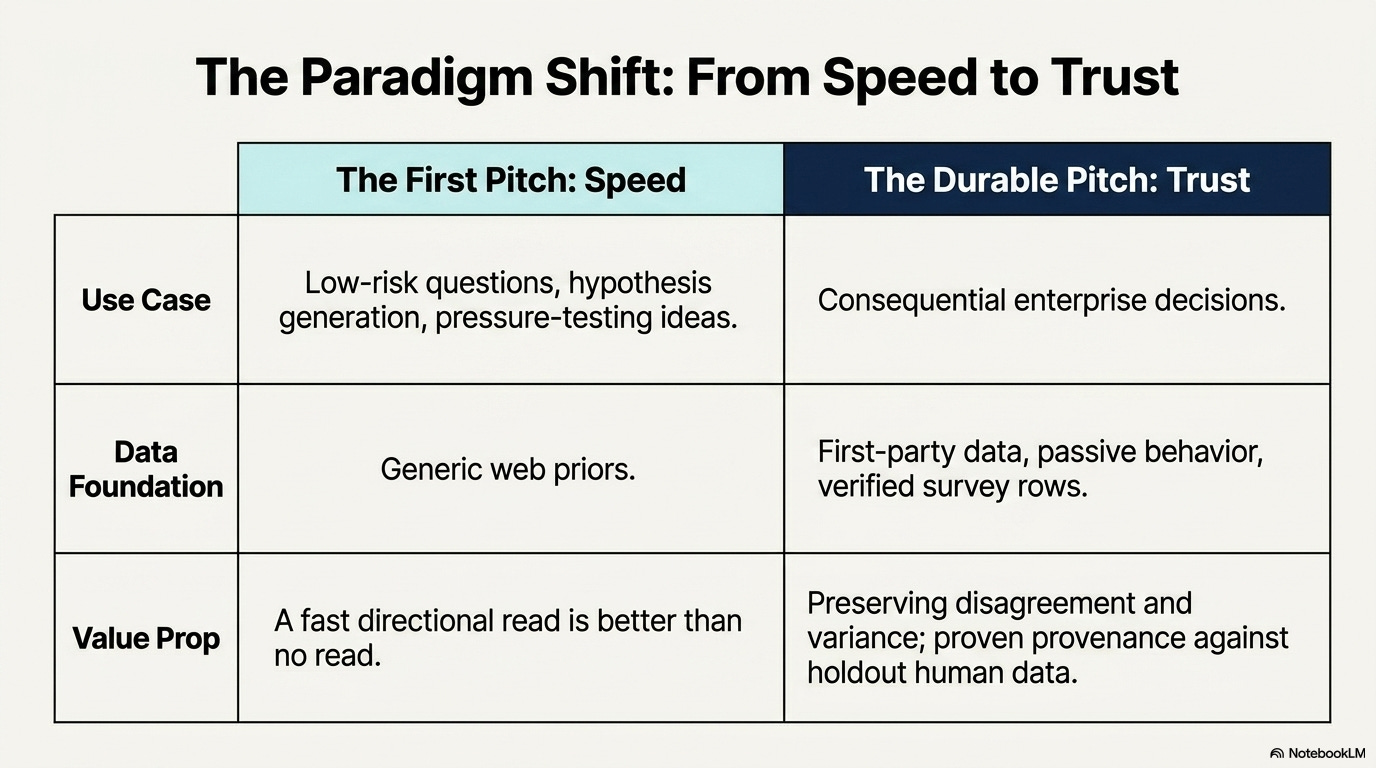
For low-risk questions, speed is enough. Synthetic respondents can help teams pressure-test ideas, identify weak assumptions, test survey logic, generate hypotheses, simulate message reactions, or rehearse stakeholder questions. In those use cases, a fast directional read may be better than no read at all.
But the more consequential the decision, the more the buyer needs to know what the synthetic output is grounded in. Is it trained on real people or generic web priors? Is it based on first-party data, panel data, passive behavior, purchase history, social signal, survey rows, qualitative transcripts, or an LLM’s averaged cultural memory? Has it been tested against holdout human data? Does it preserve disagreement and variance, or does it collapse toward the obvious answer?
The question “are synthetic respondents valid?” is too crude. The better question is: valid for what decision, grounded in what data, tested against what benchmark, refreshed how often, and governed by what boundary conditions?
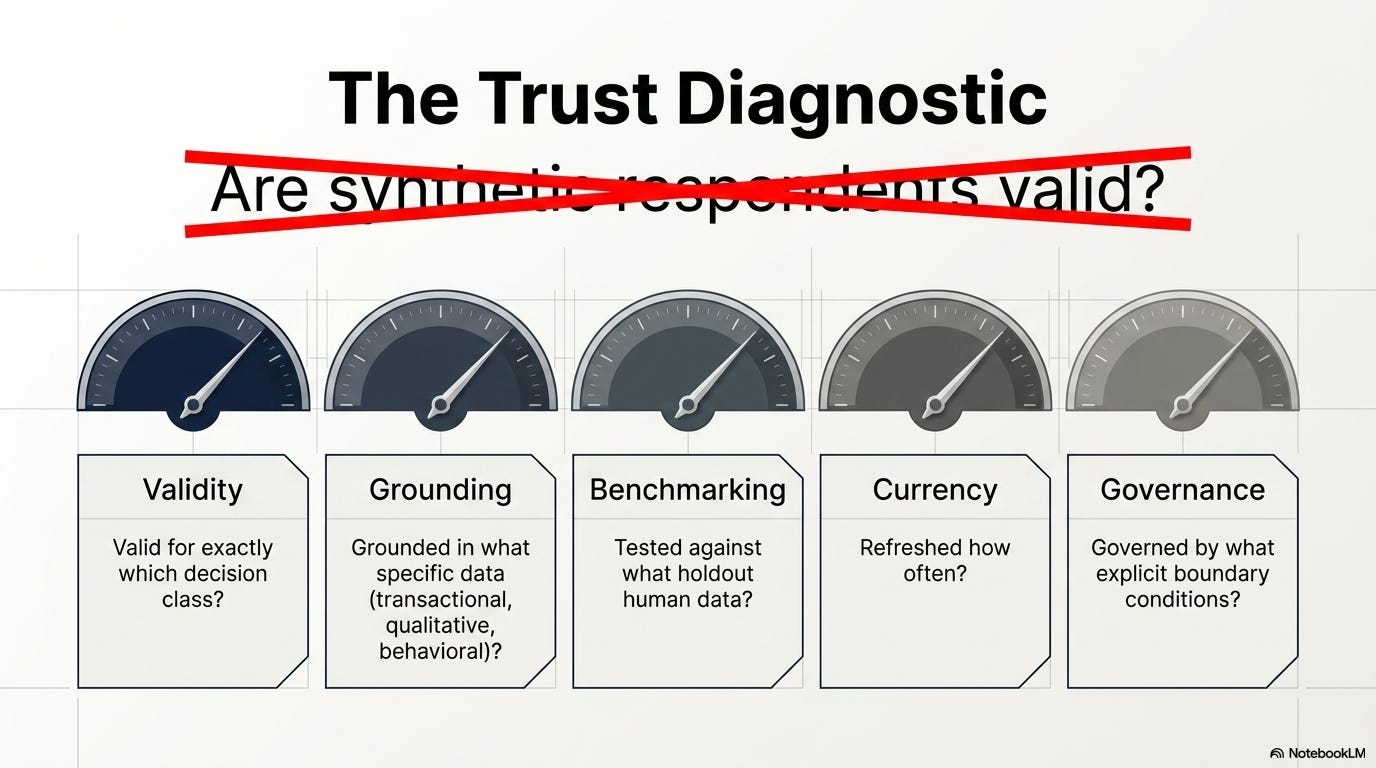
That is where the market will split. Companies with real grounding data, validation discipline, provenance, refresh logic, workflow integration, and clear use-case boundaries can become infrastructure. Companies selling lightly grounded persona chatbots will become features.
The strategic sorting has already started
The emerging market is not best understood as a vendor list. It is better understood as four strategic positions.
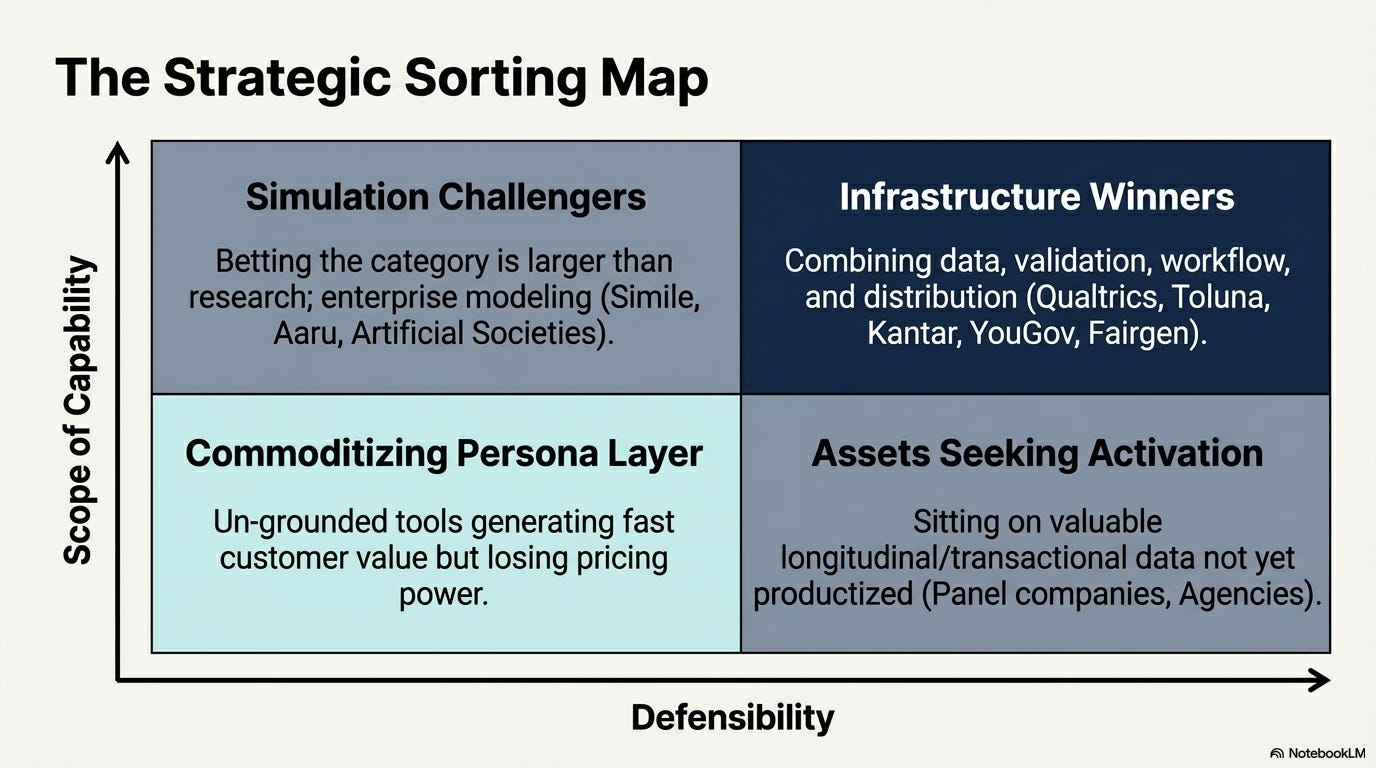
Infrastructure winners combine data, validation, workflow, and distribution. Qualtrics, Toluna, Kantar, Ipsos, NIQ, YouGov/Yabble, Fairgen, Electric Twin, Simile, Brox, and Panoplai are all trying to move in this direction, though through very different routes.
Simulation challengers are betting that the category is larger than research. Simile, Aaru, Electric Twin, and Artificial Societies are not merely trying to answer survey questions. They are trying to make human behavior more modelable for enterprise decisions.
Assets seeking activation are companies that own valuable human, behavioral, professional, transactional, cultural, or longitudinal data but have not yet fully productized it as a synthetic or hybrid decision layer. This includes many panel companies, sample platforms, agencies, data owners, and research technology platforms.
The commoditizing persona layer is where many tools will end up. They may be useful. They may grow quickly. They may generate real customer value for brainstorming, UX discovery, early concept screening, or internal workshops. But if they are not grounded, validated, and embedded, pricing power will erode as base-model capability improves.
That last point is brutal but necessary. “Synthetic respondent” is not a durable category position. It is a descriptor. The durable positions are augmentation, simulation, validation, workflow, proprietary data activation, and decision infrastructure.
The real threat is not replacement. It is abstraction.
The insights industry will be tempted to fight the wrong war.
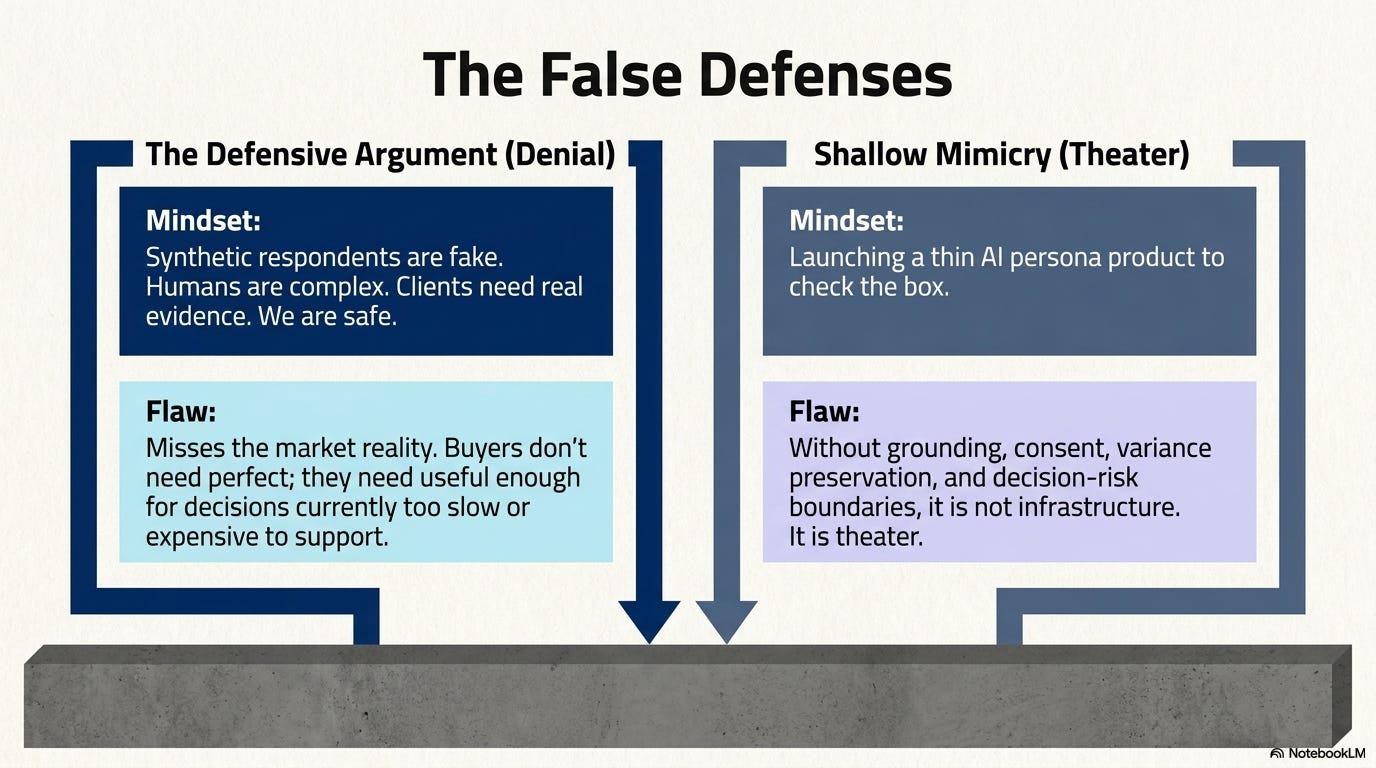
The defensive argument will be that synthetic respondents are fake, human beings are complex, clients need real evidence, and therefore the traditional research model is safe. That argument contains truth but misses the market. Buyers do not need synthetic tools to be perfect. They need them to be useful enough for a growing set of decisions that are currently too slow, too expensive, or too operationally painful to support with traditional research.
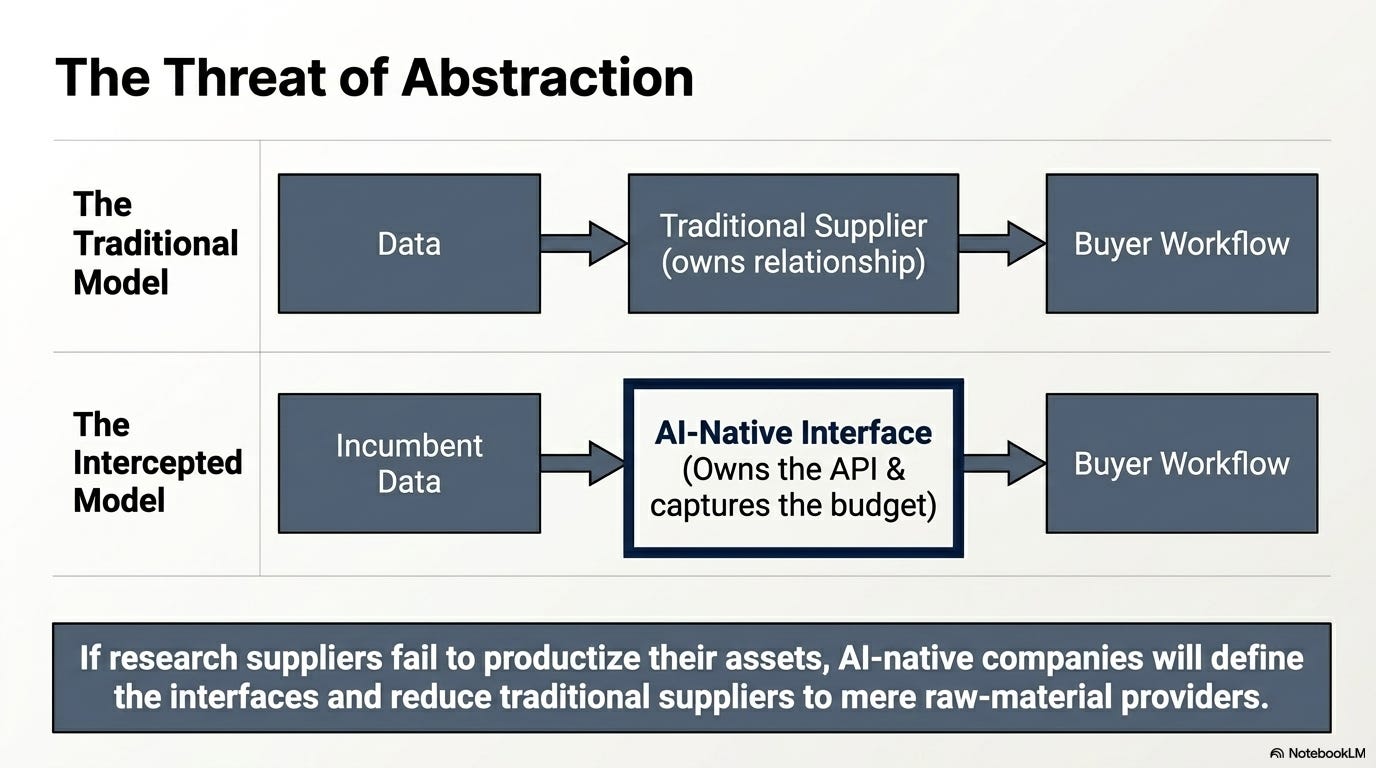
The equally bad response is shallow mimicry: every panel company, agency, and platform launching a thin AI persona product. That will not create strategic protection. If the product cannot explain grounding, consent, validation, variance, refresh, governance, and decision-risk boundaries, it is not infrastructure. It is theater.
The better response is to activate the assets the industry already has. Panel companies have verified identity, longitudinal behavior, profile data, fraud signals, consent infrastructure, and respondent relationships. Agencies have category expertise, norms, historical studies, interpretive frameworks, and client trust. Platforms have workflow control. Data companies have behavioral and transactional signal. Those are valuable inputs for synthetic and hybrid systems.
But inputs do not automatically become products. If research suppliers fail to productize those assets, AI-native companies will define the interfaces, own the APIs, capture the budget, and reduce traditional suppliers to raw-material providers.
That is abstraction. It is a bigger threat than replacement.
What this means for the insights industry
The next phase of the market will not be decided by who can generate the most plausible synthetic answer. It will be decided by who can make synthetic and hybrid data trustworthy enough to support real decisions.
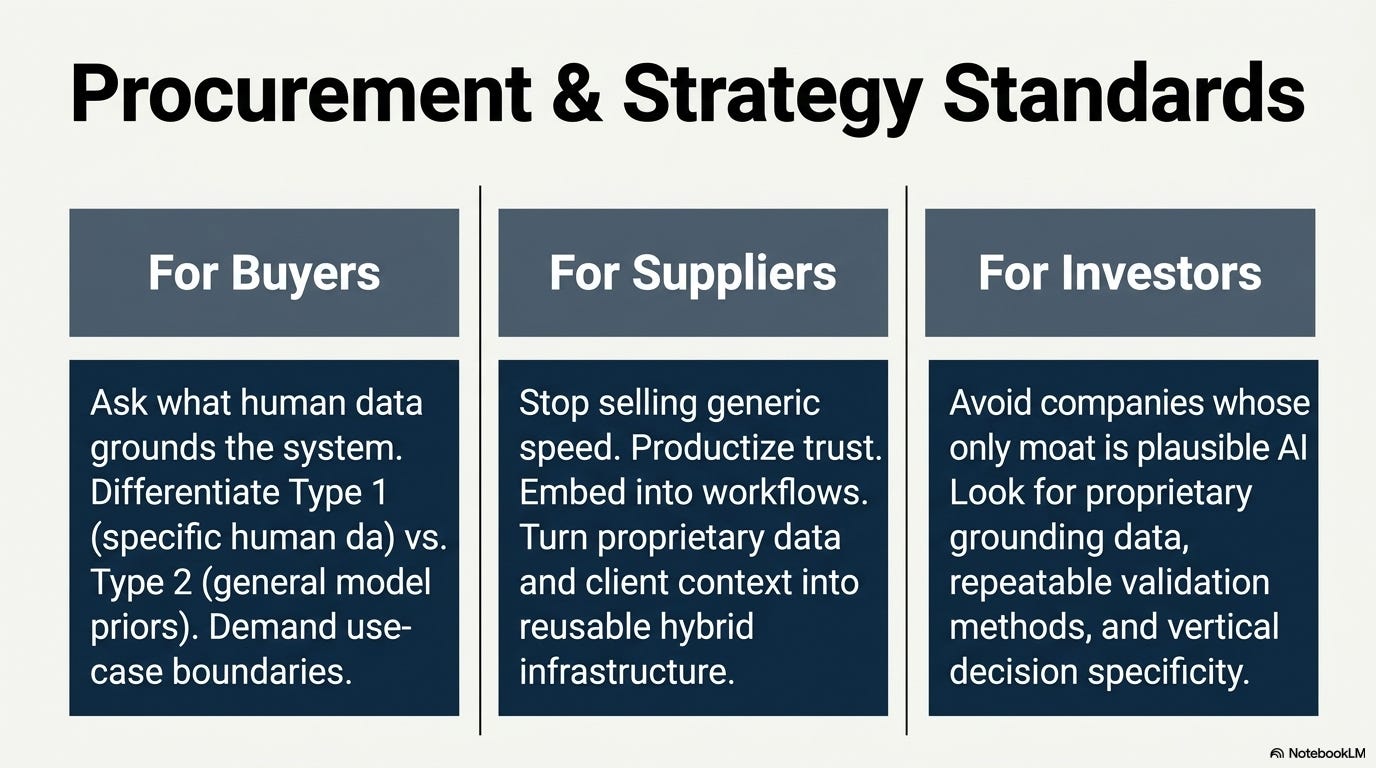
For buyers, the procurement standard should be simple. Ask what human data grounds the system. Ask whether the output is Type 1 synthetic based on a specific human dataset, Type 2 synthetic based on general model priors, or a hybrid of real and synthetic data. Ask what has been validated, against what benchmark, and for which decision class. Ask what the system should not be used for.
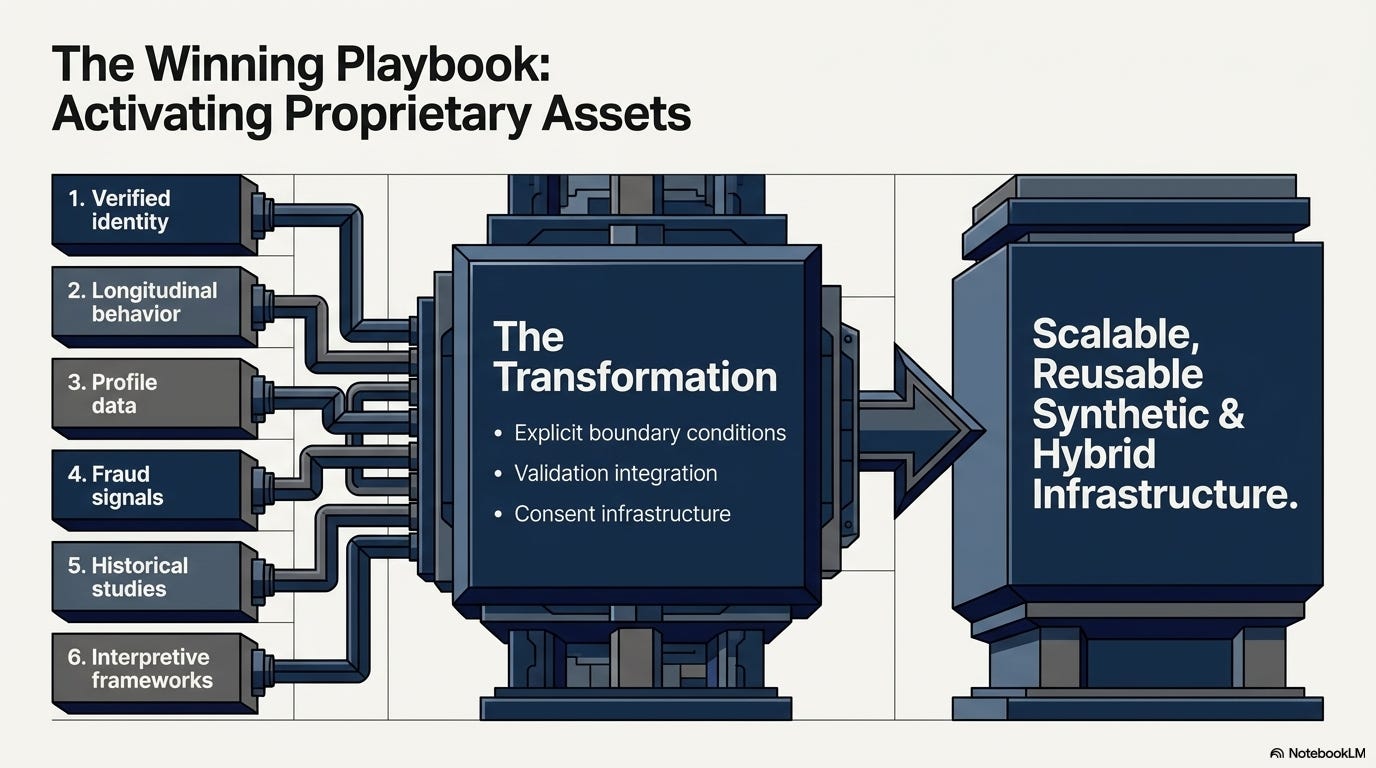
For suppliers, the imperative is sharper. Stop selling generic speed. Productize trust. Build validation into the product. Make boundary conditions explicit. Embed into workflows. Protect the human-data asset. Turn proprietary data, expertise, and client context into reusable synthetic and hybrid infrastructure.
For investors, the filter is equally clear. Avoid companies whose only moat is plausible AI output. Look for proprietary grounding data, repeatable validation methods, workflow distribution, vertical decision specificity, and evidence that the product becomes more valuable as it is used.
Synthetic sample is not going away. But the winner will not be the best fake respondent. The winner will be the company that turns verified human reality into scalable decision infrastructure.
Insight Innovation Ventures invests in AI and analytics startups across the USA and UK, with a focus on data infrastructure, research technology, and AI-native insight platforms. This post is part of an ongoing series on the structural transformation of the insights and analytics industry.