
A very senior and influential friend reached out recently with a worry we’re hearing more and more behind closed doors:
“Are we about to license our own industry out of existence?”
He’s not alone in asking. There are now active conversations and concrete projects between major AI players and sample suppliers, tech platforms, and specialist agencies to “light up” their data inside foundation models and AI-native workflows. Several sample providers are openly talking about this, and public hints match what we’re hearing privately: model vendors and hyperscalers are shopping for high-quality, labeled human data to juice their systems.
On the surface, this looks like the long‑awaited payoff for an embattled industry: high‑margin data licensing deals, new “AI partnerships,” and a way to get closer to the center of the tech stack. Underneath, it raises a hard question: are we selling shovels into a gold rush, or selling the deed to the mine?
This post is about how to think about that question without either denial or panic.
The fear behind the deals
The fear is simple and rational:
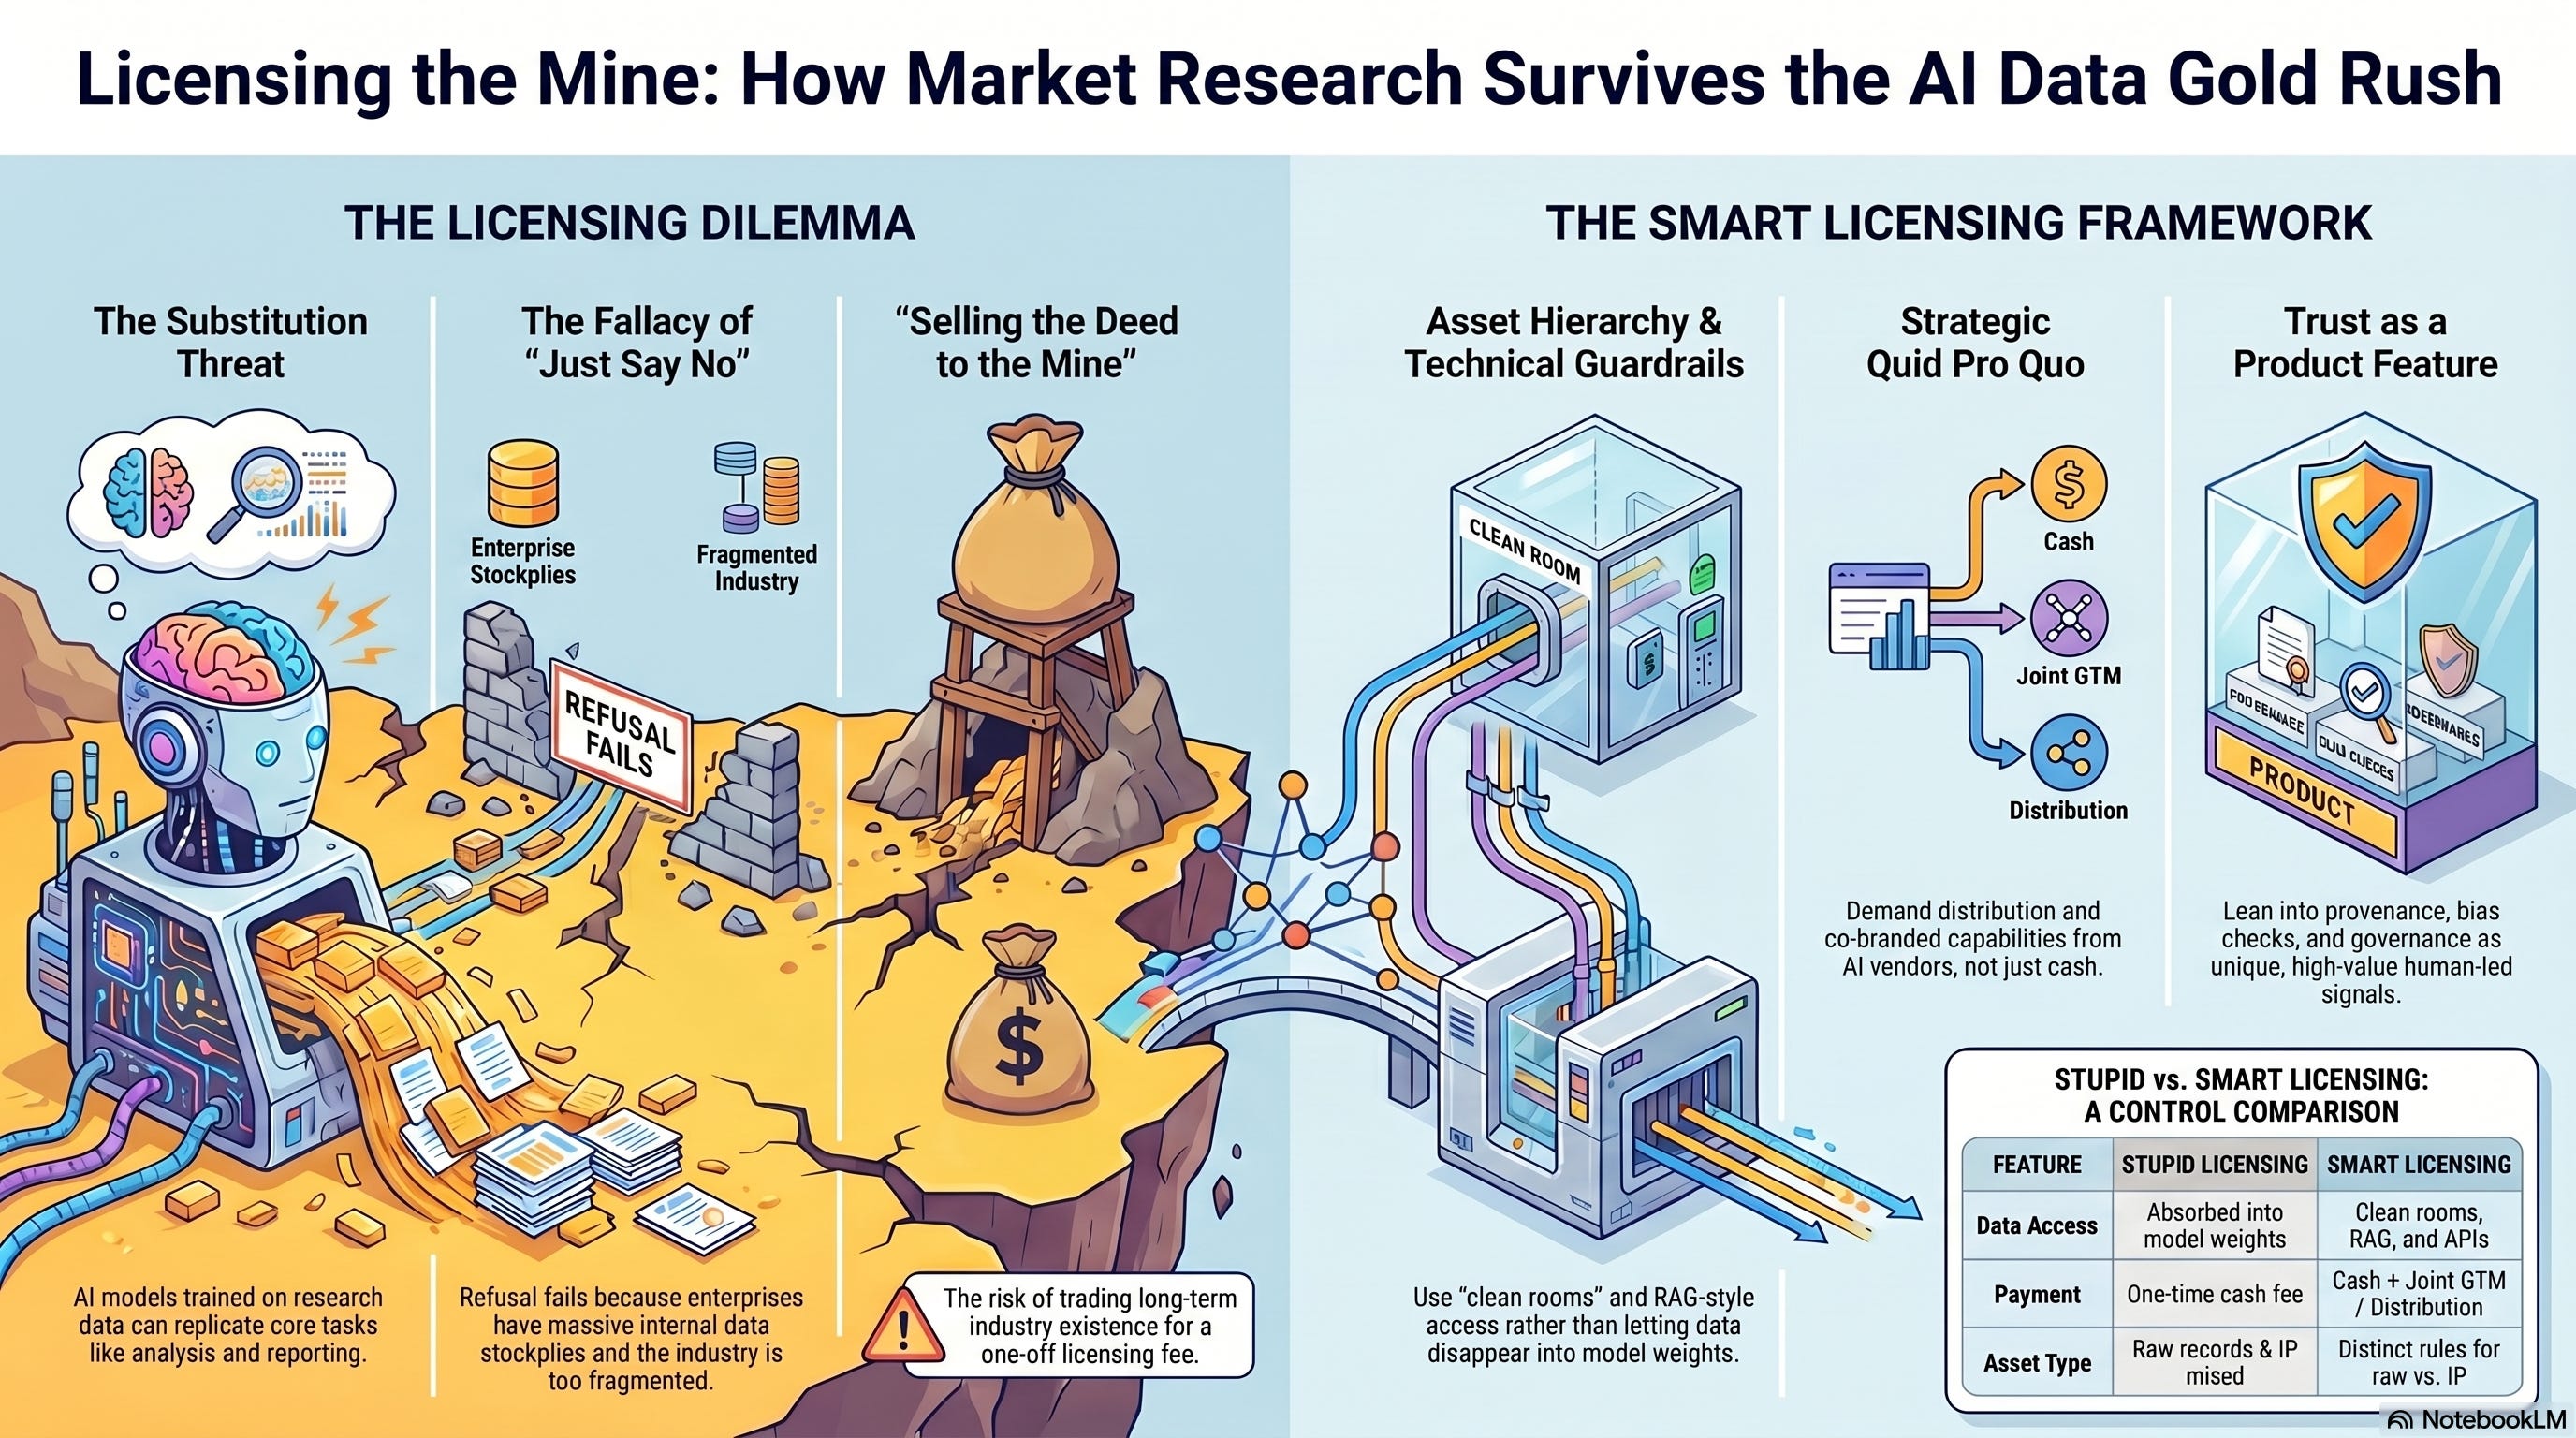
Foundation models are getting good enough that, when pointed at the right data, they can replicate big chunks of what traditional market research does: question drafting, coding, analysis, reporting, and even parts of design and experimentation.
If those models are trained on the industry’s own historical data, they could become “good enough” substitutes for a lot of bread‑and‑butter work.
In the worst case, you’ve traded a one‑off licensing fee for a world in which clients ask, “Why do I need you, when my AI agent can do 80% of this on top of my own data and a general model?”
That’s the nightmare scenario our friend was pointing to. And there’s precedent: we’re already seeing evidence that LLMs are destabilizing parts of B2B SaaS by collapsing products into “features inside the model” or inside a workflow agent. The same could absolutely happen to portions of the insights stack.
So the instinct to “just say no” to licensing is understandable. But, we think it’s just not sufficient.
Why “just don’t license” is not a strategy
I’ve heard a few senior folks float a familiar idea: maybe the solution is an informal pact: an understanding that serious players simply won’t license their archives to the model vendors.
There are three problems with that.
First, the train is already leaving the station. Even if every traditional MR firm and sample company refused to license a single row of data, enterprises sit on gigantic stockpiles of behavioral, transactional, and media exhaust, plus CRM, product telemetry, ad logs, and more. That’s more than enough for foundation models, fine‑tunes, and AI agents to power a lot of decisioning. Our refusal might slow one edge of the wedge but won’t stop displacement.
Second, the industry is structurally incapable of holding a cartel line. We are fragmented, global, and unevenly capitalized. Some companies are under real financial pressure. If a big AI player waves an eight‑figure deal at a mid‑tier supplier or tech platform, a gentleman’s agreement isn’t going to stop them. Many of those deals will be private; some are already happening.
Third, it misreads the game. The foundation models’ “objective” is not to kill market research; it’s to become the default interface for work and decision‑making. MR is collateral damage if it stays at arm’s length from operational data and activation, not the main target. As we’ve argued repeatedly here, value is migrating to tech‑plus‑services positions that sit in the flow of customer and audience decisions, not to project factories on the side.
In that context, a non‑licensing pact is like refusing to adopt email in 1995 because fax machine vendors might get hurt. It tackles a symptom, not the structural shift.
The real question: how, not whether
The more useful question is not “Should we license?” but:
Under what conditions does licensing our data make our position stronger in 3–5 years, not weaker?
That’s a very different frame than “is it morally or existentially dangerous to send data to OpenAI/Anthropic/etc.?”
In our work here we’ve been converging on a simple conclusion: the winning roles in this ecosystem are those that own or curate high‑fidelity signals, wrap them in measurement and governance, and attach them directly to business outcomes.
If you see yourself in that role, then data will absolutely move into AI systems, but you have to be obsessive about how:
What exactly are you licensing (raw responses, profiles, engineered features, segments, models)?
What rights are you granting (training, inference, evaluation, benchmarking)?
What persists in weights vs. lives in a clean room / retrieval pipeline?
What do you get back beyond money (distribution, co‑branded capabilities, privileged access, joint GTM)?
Answer those wrong, and you’ve just subsidized your own substitution. Answer them right, and you’ve traded static archives for a more central, durable role in the new stack.
What “smart licensing” could look like
Let’s make this concrete. A “smart” licensing posture, for a sample supplier, data platform, or specialist agency, might include:
Hierarchy of assets. Treat raw records, engineered features, and higher‑order IP (segments, simulators, audience‑intelligence models) as distinct asset classes with different licensing rules. Higher‑order IP should almost never be licensed in a way that irreversibly disappears into generic model weights.
Clean rooms and retrieval over weight‑poisoning. Favor architectures where your data is kept in a controlled environment and accessed at query time (RAG‑style or via APIs) rather than fully absorbed into model weights. That keeps provenance and revocability intact and reduces the chance that your unique signal simply becomes ambient “background knowledge.”
Granular rights and auditability. Contracts must be explicit about:
Whether data can be used for training vs. inference only.
Retention and deletion obligations.
Downstream sharing/sub‑licensing.
Audit rights and technical logging so you can verify compliance.
Strategic quid pro quo beyond cash. The minimum price for training rights is not just money. It’s some combination of:
Co‑developed, branded capabilities (e.g., “Audience X Intelligence powered by Model Y”).
Distribution into enterprise workflows or marketplaces.
Preferential positioning as the “research/measurement partner” in that ecosystem.
If a deal doesn’t move you closer to being the trusted signal + governance + activation layer in an AI‑mediated world, it’s probably just a one‑time harvest of your past.
The role for industry organizations
Where the “pact” idea does touch something real is the need for coordination. But instead of trying to enforce abstinence, industry bodies should be doing three things:
Set standard AI data‑licensing clauses and patterns. Publish model contracts that spell out:
Training vs. inference vs. evaluation use.
Provenance and consent requirements.
Retention, deletion, and audit provisions.
Restrictions on mixing research‑grade data with lower‑quality sources in ways that misrepresent rigor.
Define “research‑grade” provenance and trust marks. Establish criteria and certification for what counts as well‑governed data in AI systems: sampling, weighting, bias checks, synthetic vs. real, documentation, explainability. That gives both AI vendors and enterprise buyers a way to value quality beyond “more data.”
Provide governance and ethics guidance that is AI‑native, not bolt‑on. Existing codes of conduct are a good starting point, but we need explicit guidance on:
Synthetic respondents and synthetic cohorts.
Agentic systems running experiments and personalization.
Automated decisioning and profiling.
All of that helps raise the floor and creates cover for individual companies to insist on smarter deals: “We’re following the industry standard; if you want our data, here’s how it’s done.”
Where this leaves MR and adjacent players
If you believe, as we do, that AI is now the default substrate for decision‑making, the implications for the insights/analytics ecosystem look something like this:
Project‑centric, field‑and‑deck models will continue to be squeezed. Foundation models plus enterprise data will absorb a lot of “quick study” and “simple survey” demand.
Audience‑ and outcome‑centric models will grow. The real leverage sits with those who can map intent, audiences, and behaviors across channels and tie them to ROI, LTV, and risk – what we’ve been calling Decision Intelligence.
Trust, provenance, and governance become product features, not footnotes. As AI‑driven decisions scale, buyers will care a lot more about where data came from, how it was collected, and how bias and uncertainty are handled. That’s a natural strength of research‑driven organizations, if they choose to lean into it.
In that world, refusing to license data is a tactical move at best. Designing how you license, how you partner, and how you package your capabilities into the AI economy is the strategic move.
So what should leaders do right now?
If you’re running a panel, a data platform, or a specialist agency and you’re getting calls from the AI world, a few practical steps:
Inventory your data assets and classify them by strategic sensitivity and uniqueness.
Develop a default AI data‑licensing addendum that reflects the principles above; don’t start from the vendor’s paper.
Decide what you want besides money from any deal: distribution, joint product, positioning, access, or all of the above.
Engage with industry bodies not to ask for protection, but to help codify smarter patterns and trust standards.
The wrong conclusion from our friend’s concern is: “We should never license our data.” The right conclusion is closer to: “We should never license our data stupidly.”
The industry will not be saved by abstinence. It might, however, be reshaped (and in some corners strengthened) by a much more intentional approach to how our data and expertise are woven into the AI systems that are coming, whether we like it or not.
If you’re in the middle of one of these conversations with a model vendor or big platform and want to compare notes, we’d love to hear what you’re seeing.